Giving an agent memory is one of the cheapest upgrades available, and one of the most misunderstood. Here is what it costs, what it returns, and what we have learned about doing it well.
By Öykü Yıldırım, data scientist at Rewire.
AI agents are often stateless: they solve each task in isolation and carry nothing forward. For example, a support agent resolves a ticket, then meets the next one having forgotten the fix it just found. Your AI system never gets better at the job it does repeatedly.
Memory changes all that.
The question then for an engineering team is what's the ROI, how much cost and efforts to plough into it, and how best to engineer the memory.
Let's dive in.
Quantifying the impact of memory
To find out what memory is really worth, we ran one support agent that resolves a ticket by reasoning through it and querying a live database, two ways: with memory and without, holding everything else constant.
The workload was 56 real tickets processed in four sequential batches, which let us watch performance change as experience built up rather than reading a single snapshot. We scored each answer with independent LLM judges that we validated against an expert's ratings rather than trusting them blind, and tracked the cost of every task directly. We tested five memory designs: from a memoryless baseline through four memory schemes of rising sophistication, each adding one layer of capability in terms of memory saving, deduplication and memory file structure, the findings held.
Averaged over the whole workload, memory raised the quality of the agent's answers by up to 9.5 points on a 100-point scale, a 22% improvement over the same agent with none.
The more revealing figure is how that gain behaved over time. In the first batch of tickets the best memory design was barely ahead of the memoryless baseline; by the fourth it led by close to 8 points on our primary measure, and by nearly 10 on the stricter of the two judges.
Put simply, performance improved as the system learned from experience.
The best part is that cost, measured by token usage, stayed small. Memory added under 10% to the cost of a task in every design we tried, and about 7% for the design that performed best. That’s because the bill is dominated by the large fixed context every request carries - several hundred thousand tokens – not by the memory itself.
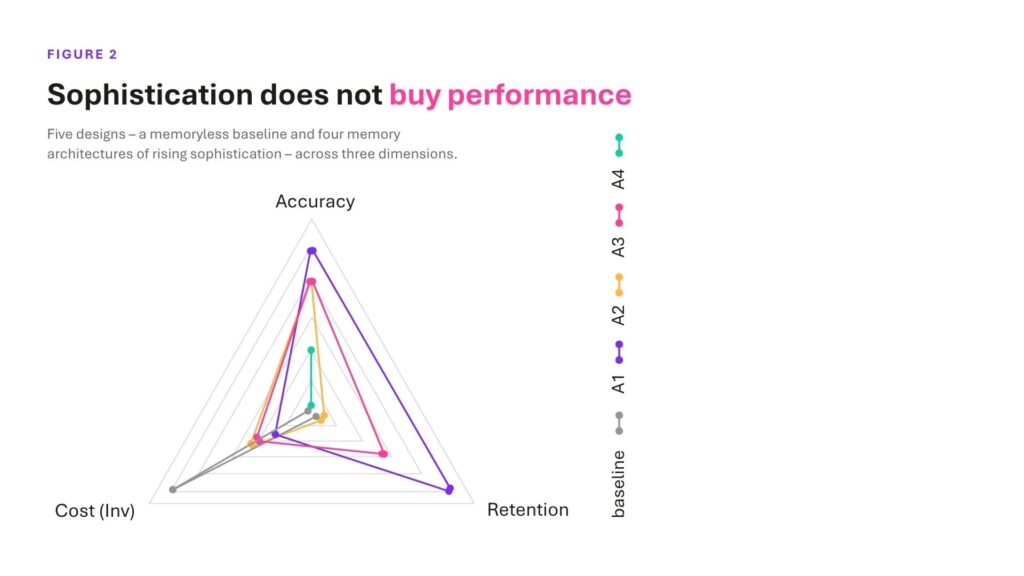
Figure 2. How five memory designs relates to three performance dimensions.
Three lessons from the experiment
In addition to making the case for memory, our experiments provided some guidance for how to maximise the impact of memory - several of them running against the intuition the AI tooling itself often encourages. Summing up:
- Memory helps, and it helps by accumulating contextual knowledge. And the payoff compounds: it is small at the start, when there is little history, and largest once experience has accumulated.
- Cleverer is not automatically better. It is tempting to tinker with memory to make it smarter - summarise raw cases, merge the similar ones, distil them into general rules, and so on. Each step is reasonable, and each throws information away. In reality, the simplest memory design, which keeps past cases in full and looks them up by similarity, was the most accurate of the five and the best at holding on to what it had learned. On the other hand, and counter-intuitively, the most elaborate architecture, which digests cases into general rules, costs the most to run and performed even less well than an agent with no memory at all.
- A tidy memory is not the same as a good one. The winning memory design filled up within the first seventeen tickets and simply dropped its oldest entries as it went, yet came out ahead. Managing memory efficiently and using it effectively are different things. Optimising the first does not deliver the second.
The bottom line
- Memory is a high-return, low-cost upgrade. Under 10% more per task buys a quality gain that compounds over time. For agents doing repetitive work, the small incremental cost is more than offset by the increased quality.
- When designing memory, start simple. In practice the simpler memory designs wins. Fund elaborate memory machinery only once you have evidence it will pay off.
- Insist on a no-memory baseline, and track quality over time. Without a baseline you cannot tell a memory that helps from one that underperforms. And performance on launch-day says little about whether the system holds over time.
- Optimise the context, not the memory module. The dominant cost is the fixed context each request carries. That, rather than the memory design, is where the real savings sit.
From our work with clients who deal with a vast amount of data and complex workflows with extensive internal loops, we’ve found time and again that memory turns a capable model into a system that gets better at its job the longer it runs, and it does so for a fraction more. The trap is assuming that cleverer memory means better memory. The real discipline is knowing what to keep, and getting that right, reliably, is what turns a promising demo into a system a business can depend on.

Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
AI capability is growing rapidly but reliability is not. The latter is critical for industrialized systems to run at scale. Here's how to build it.
Enterprise AI deployments often follow a recognisable pattern. A pilot performs well but the move from pilot to production stalls. A common explanation is that the model is not yet capable enough, and that the remedy is to wait for the next generation. Recent research suggests this explanation is incomplete. In a recent publication from Princeton University, “Towards a Science of AI Agent Reliability” (Link.) Sayash Kapoor, Arvind Narayanan and colleagues draw a distinction that is easy to overlook in procurement decisions: the difference between capability and reliability.
Capability and reliability are not the same metric
Capability describes how often a system produces the correct result. Reliability describes the nature of its failures rather than their frequency. A system may be highly capable, correct in the majority of cases, and still be difficult to depend on, because its errors are inconsistent, hard to anticipate, or hard to reverse.
To make reliability measurable, the paper borrows four properties from fields with a history of managing failure, notably aviation and nuclear engineering.
- Consistency refers to producing the same output for the same input.
- Robustness refers to performance under imperfect conditions and tool failures.
- Calibration refers to a system signalling uncertainty rather than answering with unwarranted confidence.
- Safety refers to failures being recoverable rather than catastrophic. Aviation, for reference, targets on the order of one catastrophic error per billion flight hours.
The empirical results are the most relevant part for practitioners of enterprise AI. Across fourteen models over eighteen months, the authors report that capability (also referred to as ‘accuracy’ in the paper) improved rapidly while reliability improved only modestly. In their data, each additional point of accuracy was associated with a gain of roughly a fifth to a third of a point of reliability. Consistency was among the weakest dimensions, with the same request producing a correct outcome in an estimated thirty to seventy five percent of runs depending on the model. To put that in perspective: at 75% consistency, a process fed identical inputs five times running will return the same answer every time in just 32% of cases, assuming independence. Stretch it to ten runs and the figure falls to 7.5%.
Depending on the Enterprise AI use case is, such variation may well be unacceptable. Yet it is rarely visible in a single demonstration.
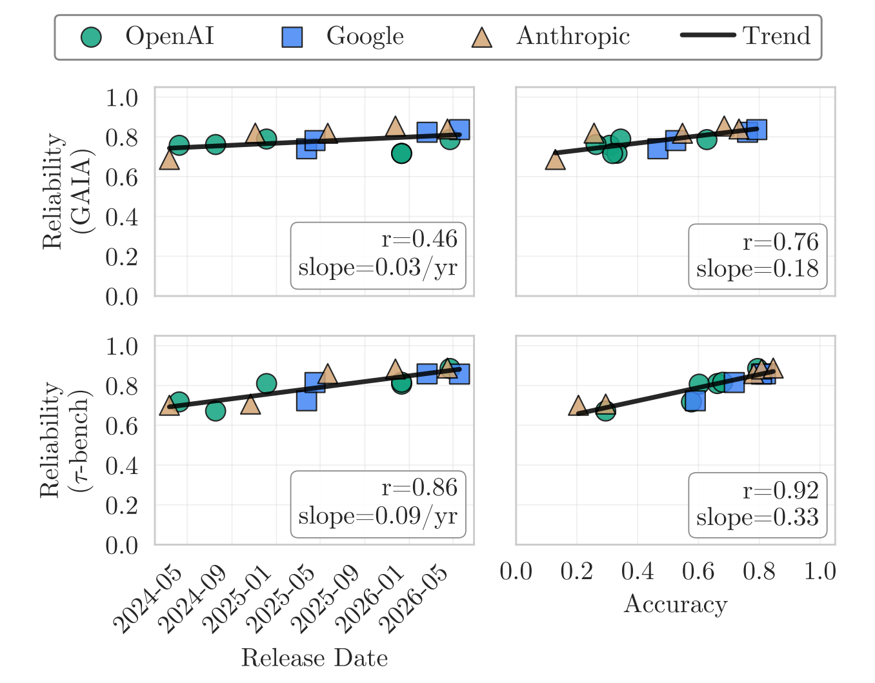
Figure 1. Figure from Kapoor, Narayanan et al., “Towards a Science of AI Agent Reliability” (2026, arXiv:2602.16666), licensed under CC BY 4.0. The shallow slopes are the key point: reliability rises only about 0.18 to 0.33 points – depending on the benchmark - per point of accuracy. https://arxiv.org/abs/2602.16666
Why reliability, rather than capability, may govern the business case
The value of an agent depends heavily on how much supervision it requires. Larger gains appear to lie in work that can run with limited oversight, and a system is usually granted that degree of autonomy only once its behaviour is consistent enough to be trusted over time.
On this reading, an agent that completes a task correctly nine times out of ten but fails unpredictably in the tenth case may still require review of all ten. This gapis one of the reasons why many pilots perform well in demonstration yet comparatively few reach production at scale.
It also helps explain why waiting for a more capable model often disappoints. Capability and reliability do not appear to advance at the same rate. A new model is likely to be more capable, but the available evidence gives little reason to expect a proportional gain in reliability.
How reliability might be engineered
The paper's framing points toward reliability as something built around a model rather than obtained from it. This reflects our own experience on client projects..
- Measure reliability as much as accuracy. A single successful demonstration provides limited evidence. Running the same task repeatedly and examining behaviour across consistency, robustness, calibration and safety gives a more representative picture than an average score. The dimensions hidden by a one-off run are often the ones that later surface in production.
- Constrain the scope. Reliability is generally easier to achieve on a narrow task with clearly defined success criteria than on an open-ended one. Broad scope tends to be where failures become unpredictable.
- Decompose long tasks. Agentic systems appear to degrade abruptly rather than gradually as tasks grow longer and larger. Breaking a long run into shorter, verifiable steps helps keep the system within the range where it remains dependable.
- Add verification and fallbacks. Independent checks on outputs, guardrails and graceful degradation can convert an unnoticed failure into a detected one. Human review can then be concentrated where an error would be costly, rather than applied uniformly.
- Evaluate procurement on reliability. Vendor comparisons that reward benchmark capability alone may select for the wrong property. Consistency and calibration deserve explicit weight.
This approach is not new. It reflects established practice in safety critical industries, where the objective is not a flawless component but a system that stays dependable when a component is not. Organisations that run regulated production environments, trading systems or industrial plants will recognise the logic, since it is broadly how those environments are already managed.
Public attention will continue to track capability, and capability is likely to keep improving. The harder question for industrial adoption may be reliability. On current evidence, the advantage lies less with the organisation that holds the most capable model, and more with the one that can turn a capable model into a system dependable enough to run with limited supervision.
Capability can be bought; reliability has to be built.
About the author
Dr. Philipp Diesinger is a data science executive with over 15 years of global experience driving AI-powered transformation across industries. He has led high-impact initiatives at Boehringer Ingelheim, BCG, and Rewire, delivering measurable value through advanced analytics, GenAI, and data strategy at scale.
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
The biopharma industry already operates like a multi-agent system, just without the agents.
Recent AI agent performance research show that AI agents now achieve near 100% success on tasks that take a human under 4 minutes, but less than 10% success on tasks over 4 hours. In other words: the longer the task, the less reliable agents are. The issue appears to be structural: making the agent smarter will not fix it. Redesigning tasks, however, can.
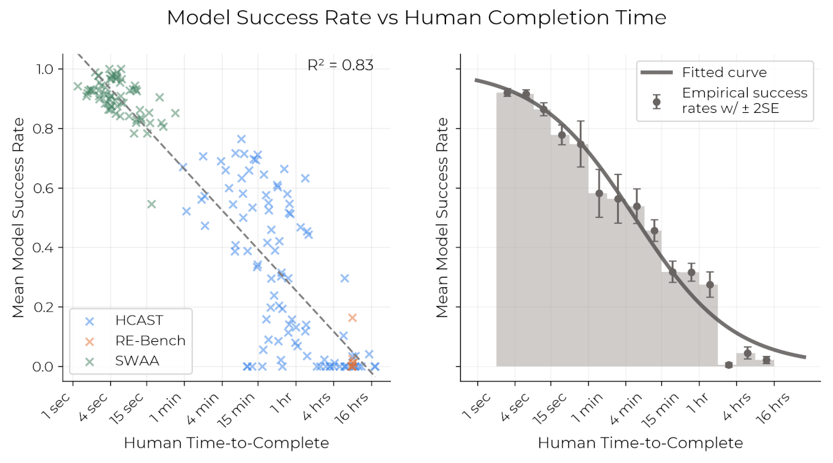
Figure 1. Model success rate vs Human completion time. Source: Kwa et al. (July 2026). Measuring AI Ability to Complete Long Software Tasks. https://arxiv.org/pdf/2503.14499
Why generalist AI agents fail, especially in biopharma
In the context of the biopharma, building one generalist agent and load it with context across regulatory, scientific, commercial, and clinical domains is inefficient. A generalist agent trying to manage regulatory compliance, synthesise scientific evidence, and sketch reimbursement pathways will hallucinate or won't go deep enough. It might be 90% right on average, but you'll never know which 10% is wrong. And one flawed reasoning step will cascade through the entire chain. In biopharma, that's an unacceptable risk.
Software engineering learned this lesson in the 2000s. Giant monolithic codebases are hard to debug or to scale. The answer was microservices, with independent modules, deployment, and validation.
The same logic now applies to agentic AI in biopharma.
The orchestration answer: specialised agents with human decision gates
Translating the logic of microservices into agentic AI systems for biopharma, the orchestration approach gives this:
- Small agents, each excellent at one narrow task. A regulatory agent that only checks compliance. A science agent that only reviews evidence. A market agent that only models reimbursement.
- Each agent can be validated independently. You can test the regulatory agent against known regulatory outcomes. You can't test a generalist agent against "everything.“
- Guardrails are built into the architecture. Validation gates between agents. If the regulatory agent flags a problem, the pipeline stops before the market agent wastes cycles on an invalid pathway. Guardrails must be structural, as we explain here.
- Humans stay in the loop at the right moments. Not reviewing every output, but sitting at decision gates between phases. The architecture defines where human judgment matters most.
- It scales. Need to add a new domain? Add a new agent. Need to improve regulatory accuracy? Retrain one agent, not the whole system.
While most industries adopting agentic AI have to build governance frameworks from scratch, biopharma already has this. The decision-gate architecture — specialised agents operating within human checkpoints — maps directly onto how pharma already works. Regulatory affairs, medical affairs, clinical development, market access: each function already has defined review cycles, sign-off requirements, and clear accountability structures. This is the multi-agent orchestration model.
Why pharma is the perfect domain for agentic systems
Developing a single drug takes 10-15 years and $1-2.6B. A significant share of that cost is coordination overhead: re-reading, re-synthesizing, waiting for reviews, reconciling conflicting inputs across functions. An analysis of 270 life sciences workflows (1200 tasks) and found that 75-85% contain tasks that could be automated or augmented by AI agents, potentially freeing 25-40% of organizational capacity.
Take medical content creation. A single piece of promotional content currently moves through approximately seven sequential review cycles across medical, legal, regulatory, and localisation. Each reviewer waits for the previous one. Average cycle: six to eight weeks.
Under an orchestrated multi-agent model, a drafting agent produces the initial version. Medical accuracy agents and regulatory compliance agents run in parallel. Localisation agents adapt for local markets simultaneously. Humans approve at two defined gates: after the initial draft and after the final review. The cycle collapses from weeks to days, while the quality controls remain intact.
The same logic applies across the pipeline: pharmacovigilance monitoring, regulatory submission drafting, protocol design, site selection, KOL mapping. In each case, the opportunity is not to replace human judgement, but to remove the coordination overhead that delays it.
The gap will be measured in pipeline years
Enterprise application of agentic systems is growing at nearly 50% compound annually, and the microservices approach is becoming the dominant architecture for AI agents. For pharma, organisations that get the orchestration right will soon gain years of pipeline advantage.
Philipp Diesinger leads the pharma Practice Area at Rewire.
Sources:
- Gartner Hype Cycle for Agentic AI, 2025 | Gartner Newsroom, Aug 2025
- SagaLLM, arXiv 2503.11951 | Du et al., "Improving LLM Reasoning with Multi-Agent Debate," arXiv 2305.14325
- IDC; PMC (NCBI PMC6372467)
- McKinsey, "Reimagining Life Science Enterprises with Agentic AI," Sep 2025
- Bain & Company, "How to Make Your Drug Launch a Success"
- DiMasi et al. (2020), PubMed 32125404
- GMP Pros / Farseer (2023)
- Grand View Research, Pharmaceutical Regulatory Affairs Market, 2024
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
The financial industry often regards regulation as a constraint. Agentic AI is turning it into an advantage.
Across banks, insurers, and asset servicers today, a similar picture emerges. On the one side, AI initiatives running in parallel without ever being absorbed into daily operations. On the other, initiatives that reliably create value. The difference between the two groups lies in the approach.
Let's focus on asset servicing in particular, because the industry tends to assume regulation is what holds it back. The opposite is closer to the truth: Fund administration, transfer agency, and the middle office already run as a sequence of controlled steps with defined owners, defined inputs, and a check at every gate. That structure is precisely the one in which AI, and agentic AI in particular, does its best work.
When AI really delivers in asset servicing
Before examining what separates success from failure, it is worth starting with what actually works. Across our projects, three factors consistently drive AI value.
- First, a clear goal inside the process. For example, "cut the time from a complete subscription pack to a cleared investor onboarding by half, so the transfer agency team can absorb a fund launch without adding headcount" is a goal a team can tackle immediately, and one against which success can be measured. On the other hand, "use AI in onboarding" will fail on both counts.
- Second, the right data, understandable and reliable. Asset servicing sits on rich, structured data: investor records, subscription and redemption flows, fund accounting ledgers, custody positions, prospectuses, etc. Here the regulated firm has a quiet advantage, because reporting obligations and audit requirements have often already forced a level of data discipline that less regulated industries lack.
- Third, results where the decision is made. In asset servicing the point of decision usually sits at a control gate: the oversight check before a NAV is released, the four-eyes review on a payment, the compliance sign-off on a new investor. Good AI does prepares the decision inside the tool the reviewer already uses, surfaces the exceptions that need a human eye, and leaves a trace of how it got there.
Where these three elements come together, impact emerges that is measurable and scalable. And it is the pattern behind the AI work that actually takes hold in regulated operations.
The structure is the advantage
It helps to be precise about why asset servicing is such fertile ground. A fund's operational life runs as a chain of distinct stages, each with its own rules, its own data, and its own responsible owner. Investor onboarding and the KYC and AML checks that gate it. Subscription and redemption processing. NAV calculation and the oversight that validates it. Reconciliation across custody and accounting. Regulatory and investor reporting at the end. Between every stage sits a handover and, almost always, a control.
This is the same architecture that multi-agent AI systems are built around. Specialized components do focused work within clear boundaries, and they hand off to one another at defined points. A single, monolithic AI asked to do everything across this chain tends to drift and to hallucinate. Specialized agents with narrow remits and clean handover points behave far more predictably, which is exactly what a regulated process requires.
The regulatory apparatus that asset servicers sometimes experience as friction is, in this light, scaffolding. The four-eyes principle is human-in-the-loop, written into the operating model long before anyone spoke of agents. AIFMD and MiFID II define who is accountable for what. DORA, which has applied to financial entities across the EU since January 2025, has pushed firms to map their operational and ICT dependencies in detail, which is the same map an agent needs to act safely. The EU AI Act, now phasing in, asks for exactly the documentation, oversight, and traceability that a well-run fund administrator already produces for its regulators. Under the CSSF and its peer supervisors, governance is not a feature to be bolted on. It is already in the building.
The constraint, then, is coordination: getting the right specialized capability to the right step, with a clean handover and a human at the gate. That is an architecture problem, and it is one this industry has been solving by hand for decades.
Figure 1
Every rule the asset servicing industry already follows is a guardrail agents need.
Together: the control stack agentic AI requires.
Tap or click a milestone for the detail behind it.
Each rule that once felt like a constraint installed a guardrail: accountability, audit trail, human oversight, a mapped environment, delegation control. That is the exact control set agentic AI needs, and the regulated firm already operates it.
Four patterns that mark successful delivery
However different mandates and maturity levels may be, the firms making visible progress attend to the same four themes.
1. Enable the right people, not only the technologists
A common assumption is that AI competence is mainly a matter of hiring more data scientists. In practice the larger leverage comes from the people who truly know the work: the fund accountants, the transfer agency officers, the oversight and quality managers who can tell a genuine exception from a benign one. They carry the context that makes an AI initiative take off. They know how a redemption will be processed, which investor data can be trusted, and where a NAV error occurs. When these people are deliberately enabled, in short, practice-oriented sessions on real cases, a technical experiment becomes a working tool. The reliable pattern is a tandem: domain expert and AI specialist working side by side, domain knowledge flowing into requirements, AI results flowing back into the process. The time from idea to first productive version typically halves.
2. Focus on a few, genuinely viable use cases
The portfolios that work are deliberately lean. Three to five use cases with visible leverage on core processes, each with a named owner and clear success criteria. Equally important is the discipline of finishing things. When a pilot has exhausted its potential, it is closed deliberately, and it makes room for the next. An illustrative picture from operations: rather than spreading effort across onboarding, reconciliation, and reporting at once, a successful team concentrates on one defined step, for example pre-checking incoming subscription documents against the legal requirements and flagging what is missing before it reaches the reviewer. The benefit shows up less in a single headline number than in a team that is noticeably relieved and a queue that clears more consistently.
3. Anchor AI directly where decisions are made
The last mile decides between AI introduced and AI in use. The firms that are consistent here build AI into the workflow: a flag inside the existing oversight tool rather than another screen, clear accountability for who acts on it, and a defined escalation for when the model is unsure. AI then becomes not an add-on but an extra pair of eyes and hands at the gate. An illustrative picture from oversight: a NAV review assistant recalculates key positions in parallel, compares them against the administrator's output, and presents only the discrepancies that exceed the NAV error threshold, with the underlying data attached. The reviewer still releases the NAV, as always. They simply see sooner where to look.
4. Treat AI as a product, not a project
Software projects have an end. AI systems do not. Successful firms give their AI systems the attention they give any production capability: a responsible owner, an operating concept, regular quality checks, versioning, and cost control. The effect is that the system stays reliable as inputs and processes change, and trust in it grows steadily. This is familiar territory for a regulated firm, because model validation, ongoing monitoring, and documented oversight are already part of the vocabulary.
Agentic AI as the natural next step
These four patterns lead naturally to where the technology is heading. The most useful way to picture agentic AI in asset servicing is a small set of specialized agents working in parallel within human decision gates. The point is that this division of labour decouples the depth of analysis from the number of people available to do it. Routine, synthesis, and scale move to the agents. The human contribution concentrates where it has always created the most value, in judgment at the gate.
Figure 2
The fund lifecycle is a chain of decision gates
Agents prepare. A person decides at every gate. Nothing passes without an audit trail.
Gate 1
Investor onboarding (KYC / AML)
|
Agent prepares Reads onboarding and KYC documents, carries out Adverse Media Screening, screens against sanctions and PEP lists, flags missing or inconsistent items. |
Human decides Compliance officer (MLRO) approves the investor. Pre-check incoming subscription packs and flag gaps before they reach the officer. |
Gate 2
Subscription and redemption
|
Agent prepares Validates dealing instructions against fund rules and cut-offs, checks cash, isolates exceptions. |
Human decides Transfer agency officer authorises the transaction. Auto-validate dealing instructions and surface only the exceptions. |
Gate 3
Reconciliation (custody and accounting)
|
Agent prepares Matches positions and cash across custodian and accounting records, classifies breaks, proposes a resolution. |
Human decides Reconciliation analyst confirms the match before NAV. Auto-reconciliation with explained, pre-classified breaks. |
Gate 4
NAV calculation and oversight
|
Agent prepares Recalculates key positions in parallel, compares against the administrator's output, flags NAV errors with the data attached. |
Human decides Oversight or fund accountant releases the NAV (four-eyes). A NAV review assistant that shows the reviewer where to look first. |
Gate 5
Regulatory and investor reporting
|
Agent prepares Compiles data across systems, drafts filings and investor reports, checks against templates. |
Human decides Reporting lead reviews and signs off. Assemble and pre-validate regulatory report packs. |
Between every stage sits a control. Agents do the preparation, a person decides at the gate, and nothing passes without an audit trail. This is the decision-gate architecture, drawn straight from the way fund administration already works.
Notice the feedback loop: regulation shapes the architecture of the AI system; the system, in turn, strengthens compliance — producing a more complete audit trail, faster.
It's not the tools. It's the capability
The firms that stay ahead build capability rather than acquire tools. Teams that understand and steer AI. Data products that are maintained and trusted. Systems that run in everyday operations instead of a test environment. And an operating logic that secures the value tomorrow as well. The most regulated corner of finance does not need to wait for the rest of the industry to work out how to govern AI. It already knows. The handover points, the four-eyes checks, the audit trail, and the documented oversight that can feel like weight are, for agentic AI, the blueprint.
Footnotes
* A further milestone reinforces the onboarding gate: the EU's 2024 anti-money-laundering package. Its single, directly applicable Anti-Money Laundering Regulation (AMLR) takes effect across the EU on 10 July 2027, and a central supervisor, AMLA, has been operational in Frankfurt since July 2025. In agent terms it sharpens a guardrail the chart already shows: verified, structured client due-diligence data and one harmonised standard for what must be checked before an investor passes.
About the authors
Dr. Philipp Diesinger is a data science executive with over 15 years of global experience driving AI-powered transformation across industries. He has led high-impact initiatives at Boehringer Ingelheim, BCG, and Rewire, delivering measurable value through advanced analytics, GenAI, and data strategy at scale.
Dorthe van Waarden leads organizations in creating tangible impact by developing and implementing advanced algorithmic systems. She is passionate about combining the power of humans with the potential of AI to achieve the best outcomes and doing this in a responsible way. Dorthe holds a MSc in Mathematics from the University of Amsterdam.
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
Organisations that govern their knowledge are about to pull ahead of their competition
By Marcel Mol and Job van Zijl, Rewire.
Companies looking to scale agentic systems quickly run into a limitation: AI is only as intelligent as the knowledge it can draw upon. While LLMs let organisations open up sources that were previously hard to utilize, such as PDFs and Word documents, the fact is that businesses aren’t documented the way they need to be to fully leverage today’s technology.
Three problems arise:
- Knowledge is tacit, internalized by employees and never written down.
- Knowledge is imperfect, with out-of-date information, discrepancies between sources, and so on.
- Knowledge is missing.
To solve these problems, we introduce the knowledge engine methodology, underpinned by a broader vision: the codified enterprise. This is how we define the winning organisations of tomorrow — where knowledge compounds rather than churns, and where agents can be deployed reliably at scale.
How the codified enterprise develops asymmetric competitive advantage
Today, organisational expertise is siloed by design: it belongs to individuals and teams, rather than the organisation as a whole. People do most of the work, and AI augments specific processes as and when needed.
Agentic AI flips is set to flip the equation around, with agents doing most of the operational work, while people oversee strategy, creativity, and edge cases. But this is only possible with a governed knowledge layer that agents and humans can query and maintain. Knowledge — rather than churning out of the door whenever someone leaves — becomes a compounding asset.
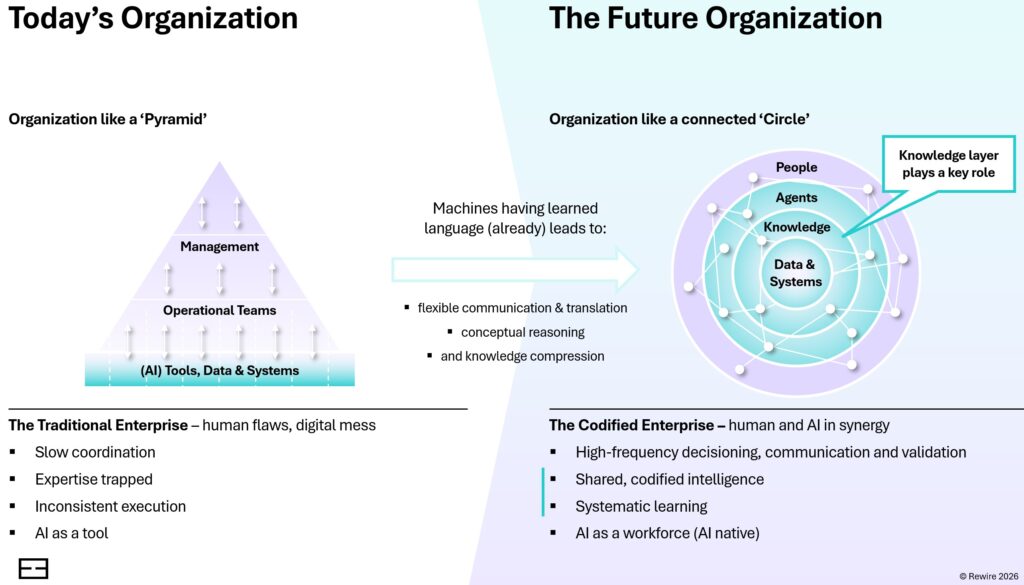
Think about what this means operationally: the codified enterprise can onboard a new agent in hours rather than weeks, because the knowledge it needs exists in structured form. It can scale a process across markets with improved institutional memory. It can respond to regulatory change by updating a knowledge graph and propagating the change systematically, rather than hoping that the right people update the right documents and that those documents get read.
The non-codified competitor, meanwhile, is still dependent on specific individuals, still recreating knowledge from scratch, still debugging agents that behave inconsistently because their prompts are patching over gaps in an unstructured information environment.
Building tomorrow’s codified enterprise
Building a codified enterprise starts with addressing three challenges:
- Making all knowledge machine-readable. The issue here is that most business knowledge lives in people’s heads, unstructured documents, or process tooling that agents cannot access. None of it is governed or current.
- Knowledge extraction taking human effort. Even where documentation exists, it is incomplete and ungoverned. The decision rules that experienced people apply intuitively — when to escalate a claim, how to handle an exception — are rarely written down. Structuring this for autonomous agent use still requires people to validate and sharpen what gets captured.
- Knowledge is never finished. Processes change. Thresholds shift. Regulations evolve. A knowledge system not designed to update continuously will decay — and agents grounded in stale knowledge become unreliable.
The knowledge engine methodology uses process documentation as input, and allows expert validation of the acquired knowledge. But there’s more to it. As a video is worth more than a thousand words, check out the video demo below. You’ll see how the knowledge engine in action, as well as:
- How knowledge can be extracted following an expert-defined ‘knowledge skeleton’, applied to building a knowledge graph from internal policy documents
- How to the extracted knowledge can be visualized, and gaps and contradictions can be made visible
- How AI can help closing these gaps by suggesting fixes, which can be approved or changed by experts
Watch the video
Curious about what a knowledge engine could do for your organisation? Get in touch!
Insights and debates from a day dedicated to transforming AI experimentation into measurable business impact.
Rewire LIVE started with a vision: to create an interactive event where participants from the business community could openly share their experiences with AI. Last week in Amsterdam, business leaders and innovators gathered to make that vision a reality.
The result exceeded expectations.
Through debates, workshops, and keynotes, attendees collectively explored what it takes to move from experimentation to meaningful impact with AI.
The next stage in the evolution of AI: introverted thinking
The day opened with a thought-provoking keynote by Wouter Huygen, Rewire CEO, who explored the paradox at the heart of Generative AI: it’s both incredibly smart and... surprisingly stupid.
Figure 1. ChatGPT, waxing digital.
So... “Are we building on shaky foundations and quicksand?”
His answer: no. Despite the limitations of current models, there is a massive opportunity overhang. With emerging toolkits and rapid innovation, today’s GenAI represents years of transformative potential.
Perhaps one of the most surprising insights was the emergence of “introverted thinking” in reasoning models – enabling transformers to refine their internal states before producing an answer. This leads to higher performance on complex reasoning tasks with smaller, more energy-efficient models. As Wouter noted, the bitter lesson of AI has, in the end, often tasted quite sweet.
Successful AI adoption: it’s all about speed and leadership
Moderated by Joe van Burik, tech editor at BNR Nieuwsradio, participants were invited to respond to a series of questions that revealed how they view AI adoption in corporate environments. Key insights included:
- 87% disagreed with the idea that AI is “just hype.”
- Most agreed that AI adoption should start with leadership, ideally from the boardroom down.
- The consensus was that it’s better to be a fast follower than a slow pioneer. Speed consistently emerged as a key success factor.
Participants then debated a range of topics, from build vs. buy strategies to regulation and productivity gains.
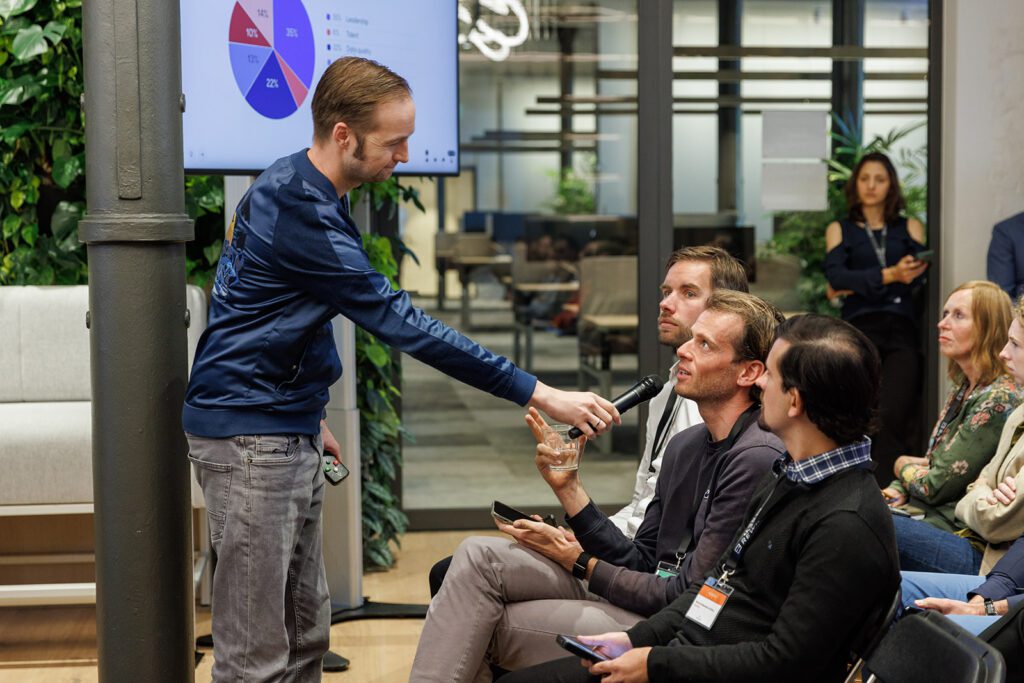
Figure 2. Joe submitting the audience to intense questioning.
The discussion concluded with a deceptively simple question:
What do you hope AI will bring to society?
We’ll leave you to ponder the resulting word cloud (below).
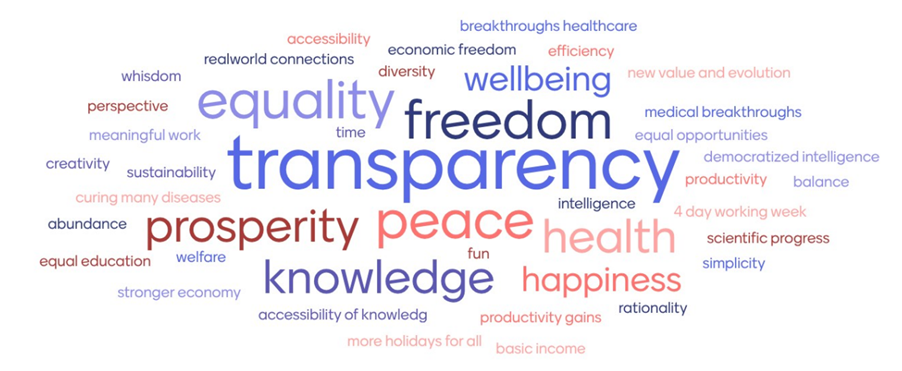
Figure 3. Every cloud has a silver lining.
Data & AI in action with hands-on workshops
The day featured four practical workshops, each tackling a different dimension of AI transformation:
- From GenAI demo to production, by Simon Koolstra & Mirte Pruppers (Rewire). Participants began with a GenAI demo and collaborated to solve the challenges that typically emerge when moving from demo to production. The exercise highlighted a hard truth: many can build demos, but scaling is where most fail.
- Reimagine your business with data, by Freek Gulden & Nanne van’t Klooster (Rewire). This session challenged participants to reimagine their businesses once data is viewed as a value stream rather than operational exhaust.
- Decentralized data leadership, by Daniëlle Bourgondië (PGGM Investments). Daniëlle led a lively discussion on what it takes for business domains to take ownership of their data and drive AI strategies. As she aptly put it: “This is not optimization. It’s reimagination.”
- Roles & responsibilities in digital transformation, by Sam van Kesteren (Royal Terberg Group) & Ties Cabo (Rewire). This workshop explored how to align business and technical roles & responsibilities to overcome some of the trickiest barriers to large-scale transformation.
Figure 4. Working out GenAI best practices: One team. One dream.
Real-world lessons from the corporate world
The day wouldn't have been complete without guest speakers detailing how AI is transforming their organizations from the inside out.
- Maarten Kramer, Chief Data Officer at a.s.r., demonstrated how agentic AI is reshaping complex insurance processes, starting with personal injury claims involving over two million documents annually. Their approach: treat AI agents like employees, with training, performance management, and oversight.
- Tim Prins, Program Director of Autonomous Operations at KPN, outlined how KPN aims to deliver the best customer service in Europe while halving costs. Agentic AI plays a central role in this ambitious transformation.
- Finally, Winifred Andriessen (VP of AI Excellence Center at KPN), Maarten Kramer (Chief Data Officer at a.s.r.), and Laura Brandwacht (Partner at Rewire) joined a panel discussion on AI’s impact on the workforce. They explored how AI is reshaping roles, the need for reskilling and upskilling, the enduring importance of human skills, and the leadership and culture required to make AI a success. The conversation underscored that AI transformation is as much about people and leadership as it is about technology.
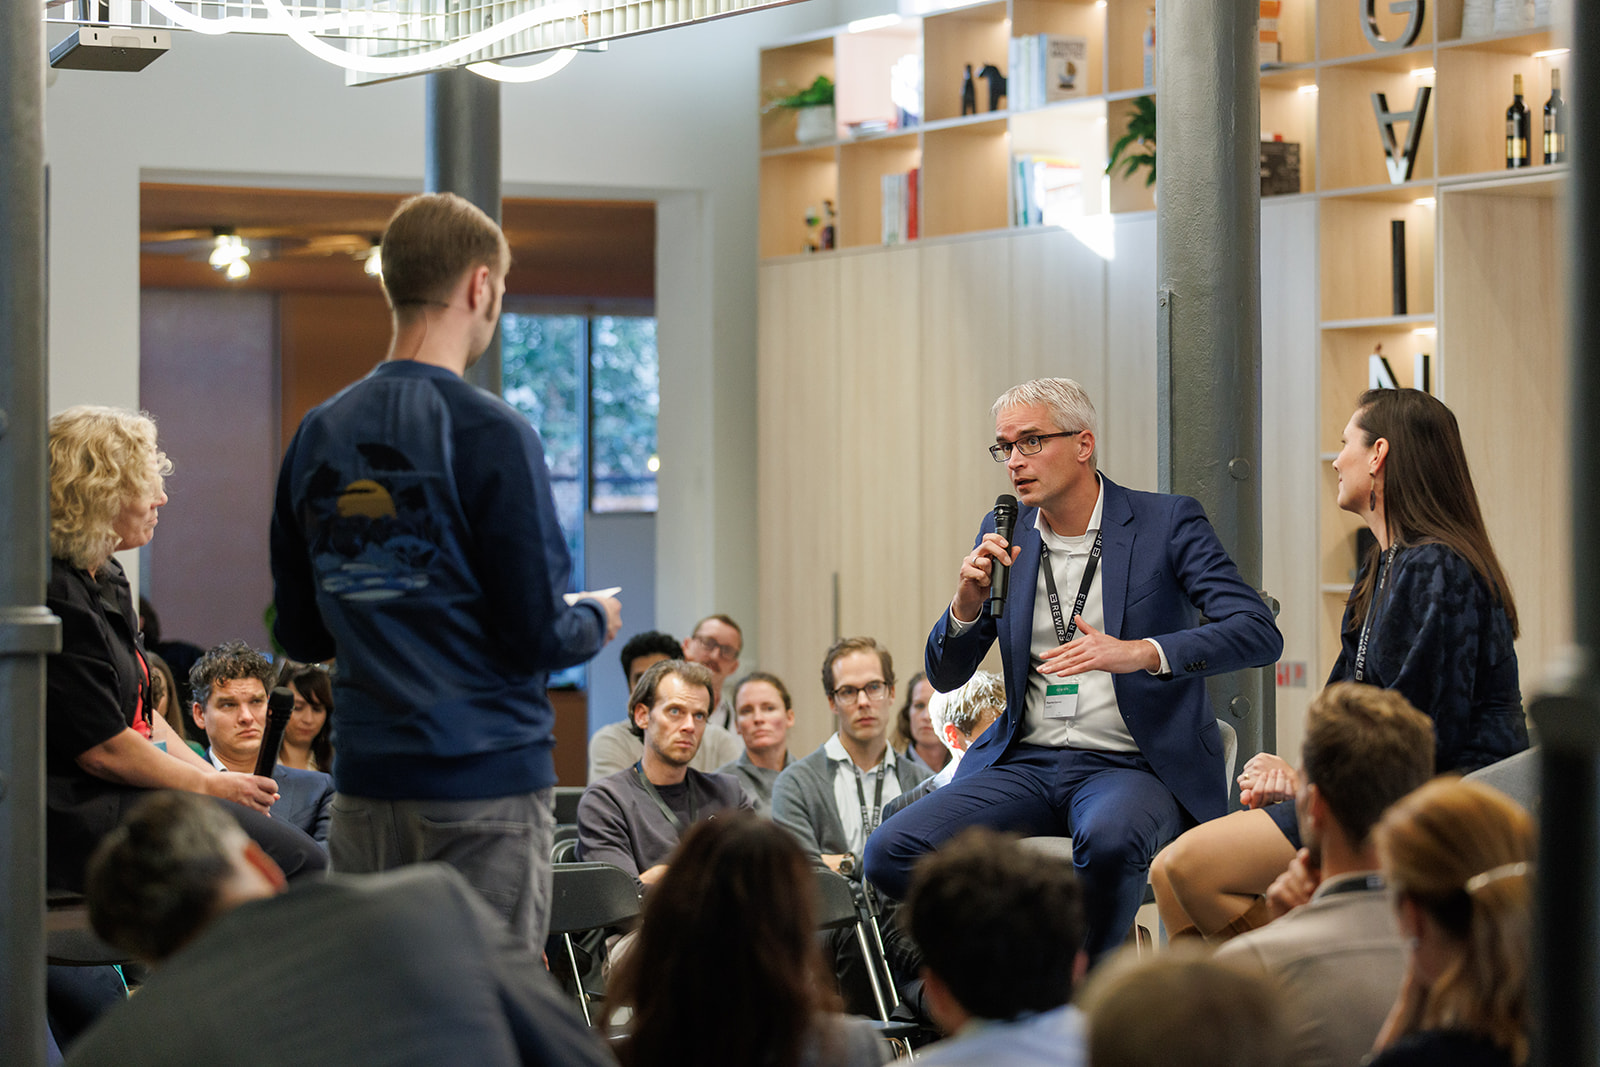
Figure 5. Not just talk: the people who are transforming businesses with AI.
Key takeaway
The day concluded with drinks and conversations went well into the evening. Reflecting on the event, two themes stood out. First, we’re at a pivotal moment in history where the playbooks for leveraging AI are still being written. Second, collaboration is key. Joining forces is the best way to reimagine your business.
Despite record investment in data platforms and products, most employers still struggle to turn data into decisions
In recent years, many organizations have focused on the technical and governance side of data management: developing products, enabling marketplaces, and defining contracts. Now, the competitive edge lies in enabling a broader base of less data-savvy consumers to turn data into actionable insight. True data democratization demands equipping people with the right skills and achieving a level of data quality that fosters trust, accelerates decisions, and drives business growth.
This blog post offers an in-depth exploration of one of three key data management trends in 2025, which we identified in this blog at the start of the year.
Kickstarting your company-wide data democratization
Empowering people begins with a clear view of your organization’s data literacy and analytics capability. Accordingly, identify skill gaps across business units, and deliver targeted trainings. We see that successful companies pair this with two things: (1) the simplification of the technology to produce and consume data, and (2) dedicated accelerator teams. The former lowers the required technical expertise; the latter paves the transformation path while the abstractions layers are still being developed. Specifically, business teams that are guided by an accelerator team fully adopt data-driven ways of working, ensuring your investment in data democratization delivers measurable business impact and competitive advantage.
Trust & quality: from building data products to building confidence
The real barrier to adoption is trust in the data produced, or rather, the lack thereof. This, in turn, stems from the gap between those who produce the data and those who rely on it to make decisions. When the producers and consumers of data operate in silos, context gets lost, quality issues linger, and decision-makers are left second-guessing the numbers. For example, if a supply chain dataset is outdated and this isn’t flagged, finance teams may base forecasts on flawed inputs, triggering a chain reaction across procurement, sales, and reporting.
So once the core data products are in place, the focus should shift to governance and collaboration. Without that human-driven quality loop, even the most advanced data product remains underused and under-trusted. With it, data becomes a reliable foundation for confident, timely decisions.
Achieving the balance between data democratization and trust
The power of data democratization lies in accelerating insights and enabling better business decisions. However, data democratization goes hand in hand with capabilities building: without the right skills, context, and support, data access can lead to confusion and misuse. And capability-building without democratization simply wastes resources.
At the same time, empowerment without trustworthy data is ineffective. Without strong collaboration between the producers and consumers of data, effective data observability, and clear communication on quality, trust diminishes. This erodes the value of democratization and leads to inaccurate decision-making.
In sum, organizations that successfully create the foundation for reliable data that drives smarter, faster and more confident decisions will focus on both people and processes, by (1) developing data literacy and confidence across the workforce via tailored trainings for the producers and consumers of data; and (2) managing data as a product with transparency, accountability, and continuous feedback loops.
Unlocking the full value of data
Market leaders reinvent and reorganize themselves around data. We can help you with this.
Explore our data management servicesThis article was written by Nanne van't Klooster, Program Manager, and Freek Gulden, Lead Data Engineer at Rewire.
Data leaders from across industries gathered to explore how to scale AI initiatives, navigate legacy systems, and unlock long-term value through strategic data management.
Last week, Rewire welcomed senior data leaders for the second edition of the Data Leadership Roundtable. Held at our Amsterdam office, the event brought together executives from a broad range of organizations – Shell, Rabobank, Heineken, AFM, KPN, Terberg, a.s.r. and many more – for an open exchange on two urgent challenges in data strategy: how to balance investment trade-offs to unlock value, and how to scale AI and data initiatives in environments dominated by legacy systems.
Industry leaders at the table.
The morning began with a plenary perspective from Rewire Partner Helen Rijkes, who reflected on the dramatic evolution of data work—from manual reporting using SPSS over 15 years ago to today's modern data environments, shaped by the shift toward domain-based data ownership and emerging technologies such as GenAI. She emphasized that the challenge isn’t building isolated use cases, but rather scaling them into sustained, organization-wide value. Success, she argued, comes from strategic balancing between consistent capability building and scaling value cases while embedding secure data access policies at scale.
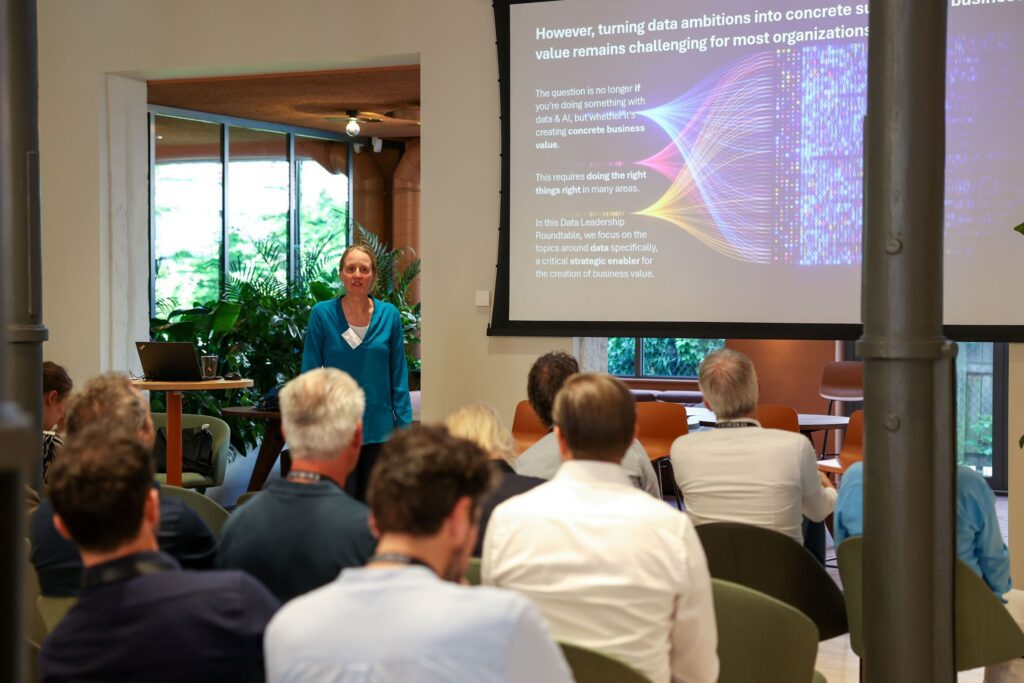
Helen Rijkes, Partner at Rewire, reflecting on the evolution of data management in recent years.
The plenary was followed by a panel discussion featuring Annemarie de Beer (AFM), Gijs Thieme (KPN), Maarten Kramer (a.s.r.), and Sam van Kesteren (Royal Terberg Group). Their conversation explored how organizations balance central and decentralized approaches to data, with many agreeing that centralized data science teams help avoid fragmentation, while local business ownership is critical for adoption. They also examined the ongoing tension between building versus buying solutions, noting that while building is attractive for strategic control and internal talent, buying can accelerate implementation—provided there's clarity on vendor limitations and alignment with business needs. Finally, the panel addressed legacy systems, emphasizing that successful transformation requires not only technical migration but also strong change management and alignment across business and IT.
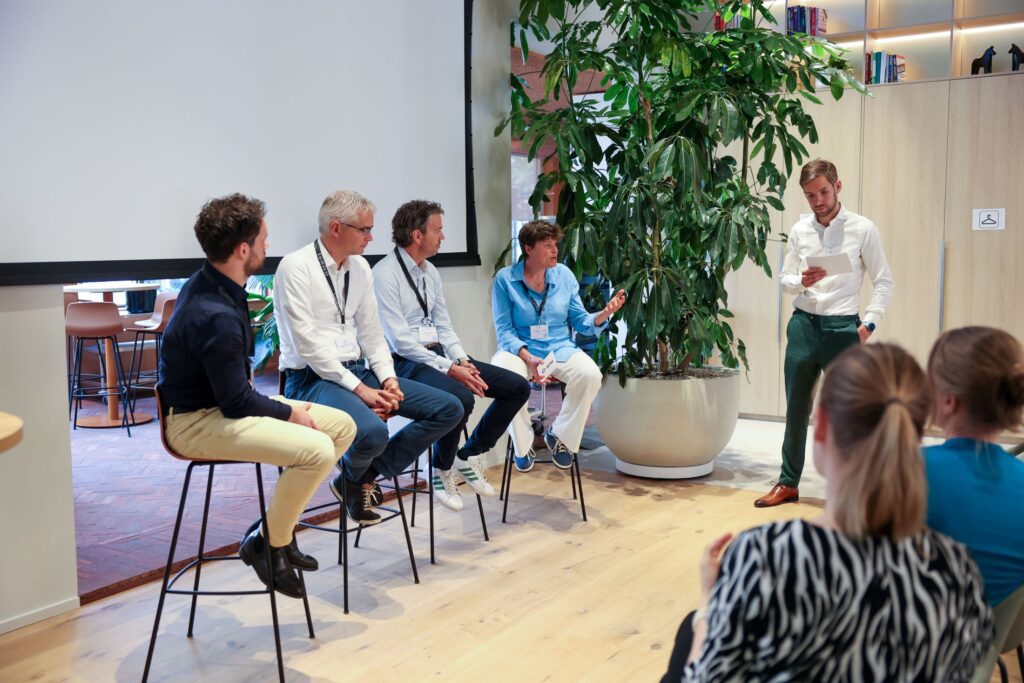
Annemarie, Gijs, Maarten, and Sam share their perspectives on common data strategy challenges
After the panel, the group split into four breakout discussions, each diving deeper into the practical realities of leading data strategy in complex environments. In one group, participants discussed the evolving role of data scientists, the importance of aligning platform decisions with long-term strategy, and the challenge of ensuring responsible access to both structured and unstructured data. Another group focused on why so many AI initiatives get stuck in the proof-of-concept phase, concluding that without the right infrastructure, skills, and business engagement, even promising pilots can fail to scale. A third group explored how to move from compliance-driven data management to a value-driven model, especially in regulated industries, while also grappling with new ethical questions introduced by AI. And in the fourth group, participants reflected on the importance of embedding AI into day-to-day decision-making, emphasizing that adoption—not just technical readiness—is what ultimately drives success.
Sharing challenges. Shaping solutions. Together.
Throughout the day, one message came through clearly: the real challenge in data and AI transformation isn’t just technical—it's organizational. Success depends on bridging silos, aligning stakeholders, embedding data into business processes, and building the trust and capabilities needed to move from experimentation to impact.
We’re incredibly grateful to all participants for their insights and participation. The conversations reaffirmed the importance of community in tackling the complex challenges when executing your data strategy in the Data & AI landscape of today. We look forward to continuing that dialogue in future roundtables.
Turning proof of concepts into lasting impact
Market leaders reinvent and reorganize themselves around data. We can help you with this.
Explore our data management servicesHow business leaders are turning AI ambition into operational reality
Last week we had the honor of welcoming industry leaders and researchers to Rewire LIVE 2025 in Frankfurt — for a day of practical insights on scaling data and AI, from vision to value at scale. With a packed agenda of keynotes, case studies, and mastermind sessions, the event zeroed in on one of the toughest challenges in enterprise AI today: how to bridge the last mile — turning promising pilots into production-grade, scalable, and trusted AI systems.
We know the answer but not the question
Rewire partner Christoph Sporleder thus opened the day by challenging common strategic pitfalls in AI adoption. Whether taking an exploratory, foundational, or holistic approach, many organizations struggle to operationalize at scale due to mismatched expectations, over-engineering, or governance complexities. His conclusion on breaking it down, balancing the transformation dimensions and going the full mile towards scale were picked up in the the powerful keynote of Simone Menne, Lufthansa’s former first female CFO. She reminded us that the real challenge of AI isn’t finding answers — it’s asking the right questions. Drawing from The Hitchhiker’s Guide to the Galaxy and her experience in leadership, Simone Menne spoke to the cultural and psychological hurdles that slow AI adoption. To overcome this we need to confront fear, foster curiosity, and prioritize education, governance, and collaboration across sectors to close the gap between potential and execution.
Dr. Peter Bärnreuther from Munich Re walked us through the rapidly growing domain of AI risks, from legal liabilities and IP issues to model drift and data bias. With over 200 AI-related lawsuits already filed globally, the urgency for transparent, testable, and auditable AI systems is mounting, and Munich Re is leading the way in also providing insurance products for AI. Nikhil Srinidhi, Partner at Rewire, illustrated the growing chasm between AI ambition and data readiness. In his talk, “Mind the Data Gap,” he highlighted the widening divide caused by poor data quality, fragmented ownership, and an expanding AI vendor landscape. His takeaway: scaling GenAI means scaling data maturity — and doing it across architecture, culture, and capability. Shannon Kehoe of QuantPi went on to emphasize that trust in AI starts with predictability and transparency. She introduced a model-agnostic platform that tests AI solutions across dimensions and presents results clearly for diverse stakeholders — from data scientists to regulators. Loïc Tilman of Elia Group shared what it takes to scale AI within a critical infrastructure operator. From evolving legacy systems to upskilling teams and ensuring sovereignty in the IT infrastructure, his talk made it clear: even in high-stakes environments, digital, data and AI transformation isn’t a luxury — it’s a necessity.
AI masterminds: defining real solutions to real challenges
The event also included interactive sessions, where Lu Yu of Novo Nordisk, Dr. Pierre Fischer of Roche and Dr. Martin Paschmann of Douglas shared real-world case studies. Participants dissected challenges ranging from siloed systems to frontline adoption. Solutions focused on data culture, internal champions, and aligning science with business needs. In one mastermind session, participants unpacked how to define the value of data products — from use-case fit and quality to cloud cost savings, time-to-insight, and user satisfaction. A key insight: value must be seen through multiple lenses — technical, financial, and strategic — and agreed upon by data, finance, and business stakeholders.

Creating a blueprint for AI Transformation
Our strategies elevate the performance of your AI applications from marginal or tactical results to unequivocal, transformational successes.
Discover our Data & AI StrategyPanel discussion: scaling AI responsibly
The day concluded with a rich panel featuring Eberhard Schnebel (Goethe University Frankfurt / Commerzbank), Dr. Stefan Rose (University of Cologne), and Paola Daniore (EPFL Lausanne), moderated by Damien Deighan, Editor of the Data and AI magazine. Topics included the privacy paradox between academia and industry; the social psychology of AI interaction in teams; Trust-building through transparency and governance; The ethical design of emotionally resonant AI systems. Their message: AI adoption is about more than models. It’s about culture, behavior, and values — and how we ensure they evolve together.
Final thoughts
Rewire LIVE 2025 reinforced a shared truth: next to data and technology, AI is a leadership challenge. The ideas, stories, and solutions shared in Frankfurt revealed a deep appetite for actionable, scalable, and human-centered approaches to Data & AI.
We’re grateful to all speakers, participants, and partners who made the day a success. Let’s keep building — together.
Want to learn more about upcoming Rewire events? Visit the Rewire events page here.
A handful of principles will set you up for success when bringing GenAI to enterprise data.
As highlighted in our 2025 Data Management Trends report, the rapid evolution of LLMs is accelerating the shift of GenAI models and agentic systems from experimental pilots to mission-critical applications. Building a proof of concept that taps a single data source or uses a few prompts is relatively simple. But delivering real business value requires these models to access consistent, high-quality data—something often trapped in silos, buried in legacy systems, or updated at irregular intervals.
To scale from pilot to production, organizations need a more structured approach—one grounded in solid data management practices. That means integrating with enterprise data, enforcing strong governance, and ensuring continuous maintenance. Without this foundation, organizations risk stalling after just one or two operationalized GenAI use cases, unable to scale or accommodate new GenAI initiatives, due to persistent data bottlenecks. The good news is that those early GenAI implementation efforts are the ideal moment to confront your data challenges head-on and embed sustainable practices from the start.
How, then, can data management principles help you build GenAI solutions that scale with confidence?
In the sections that follow, we’ll look at the nature of GenAI data and the likely challenges it poses in your first value cases. We’ll then explore how the right data management practices can help you address these challenges—ensuring your GenAI efforts are both scalable and future-proof.
Understanding the nature of GenAI data
GenAI data introduces a new layer of complexity that sets it apart from traditional data pipelines, where raw data typically flows into analytics or reporting systems. Rather than dealing solely with structured, tabular records in a centralized data warehouse, GenAI applications must handle large volumes of both structured and unstructured content—think documents, transcripts, and other text-based assets—often spread across disparate systems.
To enable accurate retrieval and provide context to the model, unstructured data first be made searchable. This typically involves chunking the content and converting it into vector embeddings or exposing it via a Model Context Protocol (MCP) server, depending on the storage provider (more on that later). Additional context is increasingly delivered through metadata, knowledge graphs, and prompt engineering, all of which are becoming essential assets in GenAI architectures. Moreover, GenAI output often extends beyond plain text. Models may generate structured results—such as function calls, tool triggers, or formatted prompts—that require their own governance and tracking. Even subtle variations in how text is chunked or labeled can significantly influence model performance.
Because GenAI taps into a whole new class of data assets, organizations must treat it differently from standard BI or operational datasets. This introduces new data management requirements to ensure that models can reliably retrieve, generate, and act on timely information—without drifting out of sync with rapidly changing data. By addressing these nuances from the outset, organizations can avoid performance degradation, build trust, and ensure their GenAI solutions scale effectively while staying aligned with business goals.
Start smart: consider data representability
Selecting your first GenAI value case to operationalize is a critical step—one that sets the tone for everything that follows. While quick experiments are useful for validating a model’s capabilities, the real challenge lies in integrating that model into your enterprise architecture in a way that delivers sustained, scalable value.
Choosing the right value case requires more than just identifying an attractive opportunity. It involves a clear-eyed assessment of expected impact, feasibility, and data readiness. One often overlooked but highly valuable criterion is data representability: how well does the use case surface the kinds of data challenges and complexities you’re likely to encounter in future GenAI initiatives?
Your first operationalized value case is, in effect, a strategic lens into your data landscape. It should help you identify bottlenecks, highlight areas for improvement, and stress-test the foundations needed to support long-term success. Avoid the temptation to tackle an overly ambitious or complex use case out of the gate—that can easily derail early momentum. Instead, aim for a focused, representative scenario that delivers clear early wins while also informing the path to sustainable, scalable GenAI adoption.
Don’t get stuck: Answer these critical data questions
The targeted approach described above delivers the early tangible win needed to get stakeholder buy-in—and, more critically, it exposes underlying data issues that might otherwise go unnoticed. Here are typical data requirements for your first GenAI use case, along with the key challenge they create and core questions you’ll need to answer.
| Requirement | Challenge | Key questions |
| Integrated information | Previously untapped information (for example, pdf documents), is now a key data source and must be integrated with your systems. | * Where is all this data physically stored? Who maintains ownership of each source? * Do you have the necessary permissions to access them? * Does the data storage tool provide a MCP server to interact with the data? |
| Searchable knowledge system | Searchable documents must be chunked, embedded, and updated in a vector database—or exposed via an MCP server—creating new data pipeline and infrastructure demands. | * Can you find a reliable embedding model for capturing the nuances in your business? * How frequently must you re-embed to handle updates? * Are the associated costs manageable at scale? |
| Context on how data is interconnected | Reasoning capabilities require explicitly defined relationships—typically managed through a knowledge graph. | * Is your data described well enough to construct such a graph? * Who will ensure these relationships and definitions stay accurate over time? |
| Retrieval from relational databases by an LLM | Models need rich, well-documented metadata to understand and accurately query relational data. | * Are vital metadata fields consistent and detailed? * Do you have the schemas and documentation required for the model to navigate these databases effectively? |
| Defining prompts, output structures and tool interface | Prompts, interfaces, and outputs must be reusable, versioned, and traceable to scale reliably and maintain trust. | * How do you ensure these prompts and interfaces are reusable? * Can you track changes for auditability? * How do you log their usage to troubleshoot issues? |
| Evaluate model outputs over time | User feedback loops are essential to monitor performance, but collecting, storing, and acting on feedback systematically is lacking. | * How do you store feedback? * How do you detect dips in accuracy or relevance? * Can you trace poor results back to specific data gaps? |
| Access to multiple data sources for the LLM | GenAI creates data leakage risks (e.g. prompt injection), requiring access controls to secure model interactions. | * Which guardrails or role-based controls prevent unauthorized data exposure? * How do you ensure malicious prompts don’t compromise the agent? |
Look beyond your first pilot: apply data product thinking -from day one
A common mistake is solving data challenges only within the narrow context of the initial pilot—resulting in quick fixes that don’t scale. As you tackle more GenAI projects, inconsistencies in data structures, metadata, or security can quickly undermine progress. Instead, adopt a reusable data strategy from day one—one that aligns with your broader data management framework.
Treat core assets like vector databases, knowledge graphs, relational metadata, and prompt libraries as data products. That means assigning ownership, defining quality standards, providing documentation, and identifying clear consumers—so each GenAI use case builds on a solid, scalable foundation.
Core data product ingredients for GenAI
Below, we outline the key principles for making that happen, along with examples, roles, and how to handle incremental growth.
1. Discoverability
Implement a comprehensive data catalogue that documents what data exists, how it's structured, who owns it, and when it's updated. This catalogue should work in conjunction with—but not necessarily be derived from—any knowledge graphs built for specific GenAI use cases. While knowledge graphs excel at modelling domain-specific relationships, your data catalogue needs broader enterprise-wide coverage. Include the metadata and examples needed for generating SQL queries, as well as references for your vector database. (This is something we find particularly useful, for example when developing AI agents that autonomously generate SQL queries to search through databases. Curated, detailed metadata, including table schemas, column definitions, and relationships allow the agents to understand the structure and semantics of the databases.) Define a scheduled process to keep these inventories current, to ensure that new GenAI projects can easily discover existing datasets or embeddings, while avoiding unnecessary re-parsing or re-embedding of data that is already available.
2. Quality standards
This includes a range of processes. From reviewing PDF documents to remove or clarify checkboxes and handwritten text to checking chunk-level completeness for embeddings, consistent naming conventions, or standardized templates for prompt outputs. Involve domain experts to clarify which fields or checks are critical, and align those standards in your data catalogue. By enforcing requirements at the source, you prevent silent inconsistencies (like missing metadata or mismatched chunk sizes) from undermining your GenAI solutions later on.
3. Accessibility
GenAI models require consistent, reliable ways to retrieve information across your enterprise landscape—yet building a custom integration for every data source quickly becomes unsustainable. As an example, at a client a separate data repository was created—with its own API and security—to pull data from siloed systems. This is where the MCP comes in handy: by specifying a standard interface for models to access external data and tools, it removes much of the overhead associated with custom connectors. Not all vendors support MCP but adoption is growing (OpenAI for example provides it). So keep that in mind and avoid rushing into building custom connectors for every system. In sum, focus on building a solid RAG foundation for your most critical, large-scale enterprise data—where the return on investment is clear. For simpler or lower-priority use cases, it may be better to wait for MCP-ready solutions with built-in search, rather than rushing into one-off integrations. This balanced approach lets you meet immediate needs while staying flexible as MCP adoption expands. (We’ll dive deeper into MCP in our next blog post.)
4. Auditability
Log every step—when doing at least make sure to include knowledge graph updates to prompts, reasoning, and final outputs—so you can pinpoint which data, transformations, or model versions led to a given response. This is especially vital in GenAI, where subtle drifts (like outdated embeddings or older prompt templates) often go unnoticed until user trust is already compromised. From a compliance perspective, this is critical when GenAI outputs influence business decisions. Organizations may need to demonstrate exactly which responses were generated, what processing logic was applied, and which data was used at specific points in time—particularly in regulated industries or during audits. Ensure each logged event links back to a clear version ID for both models and data, and store these audit trails securely with appropriate retention policies to meet regulatory, privacy, and governance requirements.
5. Security & access control
Ensure appropriate role- and attribute-based access is enforced on all data sources accessed by your model, rather than granting blanket privileges. Align access with the end-user's identity and context, preventing the model from inadvertently returning unauthorized information. Be particularly vigilant about prompt injection attacks—where carefully crafted inputs manipulate models into bypassing security controls or revealing sensitive information. This remains one of GenAI's most challenging security vulnerabilities, as traditional safeguards can be circumvented through indirect methods. Consider implementing real-time checks, especially in autonomous agent scenarios, alongside an "LLM-as-a-judge" layer that intercepts and sanitizes prompts that exceed a user's permissions or exhibit malicious patterns. While no solution offers perfect protection against these threats, understanding the risk vectors and implementing defence-in-depth strategies significantly reduces your exposure. Resources like academic papers and technical analyses on prompt injection techniques can help your team stay informed about this evolving threat landscape.
6. LLMOps
A shared, organization-wide LLMOps pipeline and toolkit gives every GenAI project a stable, reusable foundation—covering everything from LLM vendor switching and re-embedding to common connectors and tool interfaces. Centralizing these resources eliminates ad-hoc solutions, promotes collaboration, and ensures proper lifecycle management. The result: teams can launch GenAI initiatives faster, apply consistent best practices, and still stay flexible enough to experiment with different models and toolchains.
Transform Generative AI potential into performance with robust data management
Whether you win or lose in your market may soon rely on having the best Generative AI capability - and the data management setup to support it. We can help you with this.
Explore our data management servicesThe takeaway: combine your GenAI implementation with proper data management
Implementing GenAI models and agentic systems isn’t just about prompting an LLM. It’s a data challenge and an architectural exercise. By starting with a high-impact use case, you secure immediate value and insights, while robust data management practices ensure you stay in control—maintaining quality and trust as AI spreads across your organization. By adopting these principles in your very first GenAI initiative, you avoid the trap of quick-win pilots that ultimately buckle under growing data complexity. Instead, each new use case taps into a cohesive, well-governed ecosystem—keeping your AI agents current, consistent, and secure as you scale.
Those who excel at both GenAI innovation and data management will be the ones to transform scattered, siloed information into a unified, GenAI-ready asset—yielding genuine enterprise value on a foundation built to last. If you haven’t already established data management standards and principles, don’t wait any longer—take a look at our blog posts on data management fundamentals part 1 and 2.
If you’d like to learn more about building a robust GenAI foundation, feel free to reach out to us.
This article was written by Daan Manneke, Data & AI Engineer at Rewire and Frejanne Ruoff, Principal at Rewire.