Private endpoints, customer-managed keys and zero retention. The three things to insist on before proprietary data goes near a foundation model.
-By Otto Gori, Lead Cloud Engineer & Engagement Manager at Rewire.
To say that data sovereignty – i.e. owning and controlling your data and making sure that there’s no unauthorized third-party access – is top of mind would be an understatement. In the first of a series of articles, I discuss the constraints and technology options to achieve data sovereignty while still enjoying the benefits of Generative AI.
The data sovereignty challenge
Consuming Generative AI at enterprise scale creates inherent complexity and tension between the data governance of your industrial secrets and what this new tool brings as capability to your company.
While consumer AI interfaces rely on shared API endpoints with "unknown" data retention or use by third party companies like OpenAI, Anthropic and so forth, enterprise architectures require strict data isolation, zero-retention guarantees, and precise lineage tracking.
The central thesis of modern AI architecture is straightforward: Enterprises do not necessarily need to build foundation models from scratch to achieve full data sovereignty. By abstracting the intelligence layer from the underlying data hosting layer, organizations can maintain absolute administrative cryptographic and operational control over their proprietary assets while leveraging managed foundation models.
So problem solved? Not quite. That’s because there are a bunch of requirements that constrain data governance. Let’s review some of the most critical ones.
The “non negotiables” of production-grade data governance
Production readiness requires moving beyond raw API calls to robust control planes.
The first pillar of control is network perimeter isolation. Enterprise AI solutions must route inference prompts and fine-tuning artifacts through private link endpoints, preventing third-party telemetry or sensitive payload traffic from traversing the public internet.
The second pillar centers on zero data retention (ZDR) and cryptographic boundaries. Model providers must operate strictly as stateless processors. Customer prompts, context windows, and retrieval-augmented generation (RAG) embeddings must never be used to train foundational weights or stored in persistent provider logs. Furthermore, customer-managed encryption keys (CMEK) ensure that fine-tuned weights and vector embeddings remain unreadable to the platform provider at rest.
The third pillar is cloud agnosticism. Relying on proprietary toolchains creates strategic vulnerabilities. A resilient architecture decouples model invocation from business logic, treating large language models as interchangeable processing units behind unified API gateways.
But before we go agnostic, which solutions out there follow these principles, and you can easily interface with? Data sovereignty after all is not strictly defined by where your models run, but by who controls the compliance, encryption keys, network routes, retention logs and the physical location of the datacenters.
An overview of common technology solutions – and pointers on how to choose
While self-hosted open-source models (e.g., Llama, Mistral) on dedicated GPU clusters offer maximum theoretical control, they carry significant operational overhead. AWS Bedrock, Google Cloud Vertex AI, and Azure Foundry together control roughly 70% of the European hyperscale market, so your engineering team is almost certainly familiar with one or more of them. They provide the fastest path to production because they allow enterprises to apply existing governance policies, identity management (IAM), and network perimeters to foundation models without maintaining bare-metal infrastructure. They also greatly reduce the engineering challenge of implementing this solution in-house. Not to mention the very attractive price of experimentation when comparing with the acquisition of expensive hardware.
Rather than evaluating or recommending a single platform, this overview presents the primary enterprise options as reference. Each offers distinct governance models and isolation configurations; selecting the optimal solution depends entirely on your organization’s unique regulatory mandates and existing cloud footprint.
Amazon Bedrock
Implements a serverless API paradigm centered on strict data boundary enforcement. Prompts and completions are rendered statelessly and can be configured for zero content logging or model training by third-party model providers. Through AWS PrivateLink, inference calls remain entirely within the customer’s Amazon VPC. Fine-tuning jobs for models like Meta Llama or Amazon Titan run inside, isolated compute environments, encrypted with customer-managed AWS KMS keys.
Google Cloud Vertex AI
Provides integrated enterprise governance through Private Service Connect and VPC Service Controls. It allows organizations to deploy Gemini models alongside custom open-weight architectures within a controlled security perimeter. Vertex AI enforces strict zero data retention policies for enterprise contracts and integrates natively with Cloud KMS, guaranteeing that prompt histories and customer embeddings remain isolated within the enterprise boundary.
Azure Foundry
Enterprise-grade orchestration across Azure OpenAI Service and open-source model catalog offerings. By anchoring infrastructure in Azure Virtual Network private endpoints and Microsoft Entra ID role-based access control, organizations prevent data exposure. Azure Foundry ensures that customer data is never used to train global base models, while enabling fine-tuning, RAG indexing in Azure AI Search, and prompt evaluation under strict data loss prevention policies.
Figure 1. A comparative matrix of the three most common solutions
| Feature | Amazon Bedrock | Google Cloud Vertex AI | Azure AI Foundry |
|---|---|---|---|
| Primary network isolation | AWS PrivateLink | VPC Service Controls and Private Service Connect | Azure Private Link |
| Key management | AWS KMS (CMK) | Cloud KMS (CMEK) | Azure Key Vault (CMK) |
| Zero data retention | Configurable and contractual | Contractual guarantees | Opt-in and contractual |
| Multi-model flexibility | Broadest serverless API catalogue | Native Gemini plus custom open-weight support | Strong OpenAI integration plus open-source catalogue |
| Identity and access | AWS IAM | Google Cloud IAM | Microsoft Entra ID (RBAC) |
Scroll the table sideways to see all three platforms.
Choosing the right platform usually comes down to where your data already lives and which models your workloads demand, but in a nutshell, this is a quick reference if you are still in doubt:
Choose AWS Bedrock if: Your application architecture is already heavily invested in AWS. Bedrock's serverless approach makes model swapping painless via unified APIs, and its PrivateLink integration is rock-solid for strict VPC isolation. Bedrock shines when you want to experiment with different model providers (like Anthropic vs. Meta) without rewriting your orchestration logic or managing compute instances.
Choose Google Cloud Vertex AI if: You require deep integration with BigQuery to leverage advanced data analytics or want to fine-tune open-weight models alongside Google’s Gemini family. Vertex AI’s VPC Service Controls provide unmatched security perimeters if you are already handling complex data pipelines on GCP, though configuring the security boundaries requires rigorous IAM hygiene.
Choose Azure Foundry if: Your enterprise relies heavily on the Microsoft ecosystem (Azure VNets, Microsoft Entra ID) or requires direct access to OpenAI’s frontier models within a dedicated enterprise tenant. Azure makes identity management and Role-Based Access Control (RBAC) seamless through Entra ID, making it a favorite for security teams to audit end-user access to RAG pipelines.
Conclusion
Achieving true data sovereignty in enterprise Generative AI is ultimately an architectural discipline, not a product feature. While Amazon Bedrock, Google Vertex AI, and Azure Foundry offer the stateless invocation, private perimeters, and encryption capabilities required for compliance, no managed platform will solve governance for you out of the box. Sovereign AI isn't about where the intelligence is hosted—it’s about who holds the keys to the kingdom.
And as a personal hint: use KMS Keys for your kingdom =)
Sources - If you would like to extend your research, start here.
Google Cloud Vertex AI
- Google Cloud Generative AI Privacy & Data Governance Commitment. Google’s explicit contractual commitments regarding data ownership, non-retention of prompts/responses for base model training, and adherence to enterprise privacy standards.
- Vertex AI Data Governance & Security Controls. How Vertex AI protects the complete AI life cycle—from training to runtime inference—within enterprise perimeters.
- Vertex AI Dataset Encryption with CMEK. Technical implementation of Customer-Managed Encryption Keys (CMEK) via Google Cloud KMS for encrypting Vertex AI datasets and model artifacts.
- VPC Service Controls Documentation. Mitigating data exfiltration risks by enforcing private network boundaries and isolating multi-tenant Google Cloud resources.
Amazon Bedrock
- Amazon Bedrock Security, Privacy, and Responsible AI. Amazon Bedrock’s core data policy, establishing that customer inputs and outputs are never shared with model providers or used to train base foundation models.
- [Data Protection in Amazon Bedrock (User Guide). Encrypting custom models, agent sessions, and knowledge bases using AWS Key Management Service (KMS) customer-managed keys.
- Amazon Bedrock VPC & PrivateLink Setup. Establishing private VPC network connectivity through AWS PrivateLink to execute inference requests without exposing traffic to the public internet.
Azure Foundry / Azure OpenAI
- Data, Privacy, and Security for Models Sold in Microsoft Foundry. Proof that prompts, generated content, and fine-tuning data in Azure Foundry are strictly customer-isolated, double-encrypted at rest, and omitted from base model training.
- Data, Privacy, and Security for Azure Foundry Agent Service. Specific data isolation rules for stateful entity memory, RAG integrations, and custom agent tool execution.
- Security Features in Azure Content Understanding & Foundry Tools. Implementing Virtual Network (VNet) private endpoints, Microsoft Entra ID role-based access control (RBAC), and Customer-Managed Keys (CMK) within Azure AI infrastructure.

Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
Giving an agent memory is one of the cheapest upgrades available, and one of the most misunderstood. Here is what it costs, what it returns, and what we have learned about doing it well.
By Öykü Yıldırım, data scientist at Rewire.
AI agents are often stateless: they solve each task in isolation and carry nothing forward. For example, a support agent resolves a ticket, then meets the next one having forgotten the fix it just found. Your AI system never gets better at the job it does repeatedly.
Memory changes all that.
The question then for an engineering team is what's the ROI, how much cost and efforts to plough into it, and how best to engineer the memory.
Let's dive in.
Quantifying the impact of memory
To find out what memory is really worth, we ran one support agent that resolves a ticket by reasoning through it and querying a live database, two ways: with memory and without, holding everything else constant.
The workload was 56 real tickets processed in four sequential batches, which let us watch performance change as experience built up rather than reading a single snapshot. We scored each answer with independent LLM judges that we validated against an expert's ratings rather than trusting them blind, and tracked the cost of every task directly. We tested five memory designs: from a memoryless baseline through four memory schemes of rising sophistication, each adding one layer of capability in terms of memory saving, deduplication and memory file structure, the findings held.
Averaged over the whole workload, memory raised the quality of the agent's answers by up to 9.5 points on a 100-point scale, a 22% improvement over the same agent with none.
The more revealing figure is how that gain behaved over time. In the first batch of tickets the best memory design was barely ahead of the memoryless baseline; by the fourth it led by close to 8 points on our primary measure, and by nearly 10 on the stricter of the two judges.
Put simply, performance improved as the system learned from experience.
The best part is that cost, measured by token usage, stayed small. Memory added under 10% to the cost of a task in every design we tried, and about 7% for the design that performed best. That’s because the bill is dominated by the large fixed context every request carries - several hundred thousand tokens – not by the memory itself.
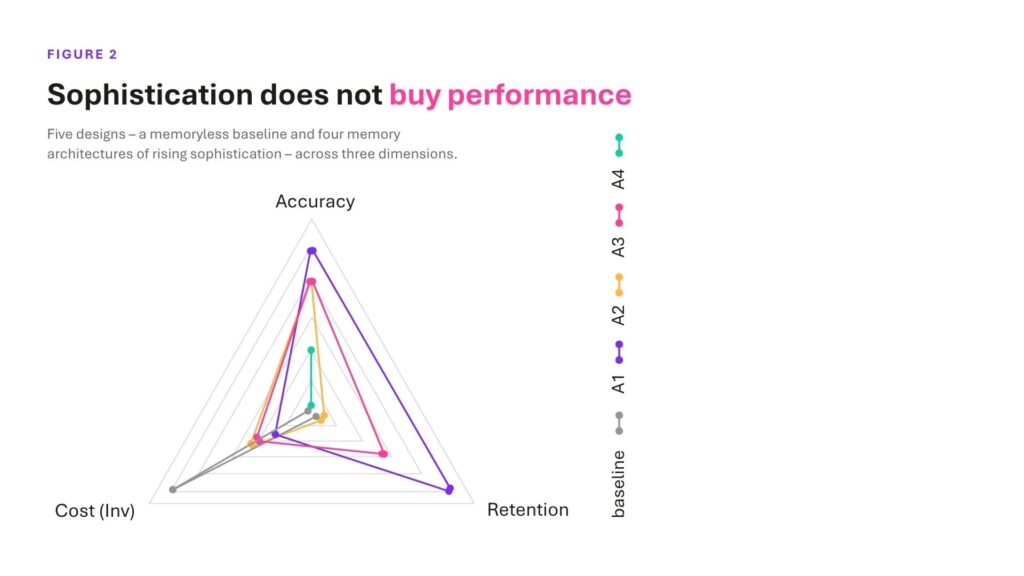
Figure 2. How five memory designs relates to three performance dimensions.
Three lessons from the experiment
In addition to making the case for memory, our experiments provided some guidance for how to maximise the impact of memory - several of them running against the intuition the AI tooling itself often encourages. Summing up:
- Memory helps, and it helps by accumulating contextual knowledge. And the payoff compounds: it is small at the start, when there is little history, and largest once experience has accumulated.
- Cleverer is not automatically better. It is tempting to tinker with memory to make it smarter - summarise raw cases, merge the similar ones, distil them into general rules, and so on. Each step is reasonable, and each throws information away. In reality, the simplest memory design, which keeps past cases in full and looks them up by similarity, was the most accurate of the five and the best at holding on to what it had learned. On the other hand, and counter-intuitively, the most elaborate architecture, which digests cases into general rules, costs the most to run and performed even less well than an agent with no memory at all.
- A tidy memory is not the same as a good one. The winning memory design filled up within the first seventeen tickets and simply dropped its oldest entries as it went, yet came out ahead. Managing memory efficiently and using it effectively are different things. Optimising the first does not deliver the second.
The bottom line
- Memory is a high-return, low-cost upgrade. Under 10% more per task buys a quality gain that compounds over time. For agents doing repetitive work, the small incremental cost is more than offset by the increased quality.
- When designing memory, start simple. In practice the simpler memory designs wins. Fund elaborate memory machinery only once you have evidence it will pay off.
- Insist on a no-memory baseline, and track quality over time. Without a baseline you cannot tell a memory that helps from one that underperforms. And performance on launch-day says little about whether the system holds over time.
- Optimise the context, not the memory module. The dominant cost is the fixed context each request carries. That, rather than the memory design, is where the real savings sit.
From our work with clients who deal with a vast amount of data and complex workflows with extensive internal loops, we’ve found time and again that memory turns a capable model into a system that gets better at its job the longer it runs, and it does so for a fraction more. The trap is assuming that cleverer memory means better memory. The real discipline is knowing what to keep, and getting that right, reliably, is what turns a promising demo into a system a business can depend on.
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
AI capability is growing rapidly but reliability is not. The latter is critical for industrialized systems to run at scale. Here's how to build it.
Enterprise AI deployments often follow a recognisable pattern. A pilot performs well but the move from pilot to production stalls. A common explanation is that the model is not yet capable enough, and that the remedy is to wait for the next generation. Recent research suggests this explanation is incomplete. In a recent publication from Princeton University, “Towards a Science of AI Agent Reliability” (Link.) Sayash Kapoor, Arvind Narayanan and colleagues draw a distinction that is easy to overlook in procurement decisions: the difference between capability and reliability.
Capability and reliability are not the same metric
Capability describes how often a system produces the correct result. Reliability describes the nature of its failures rather than their frequency. A system may be highly capable, correct in the majority of cases, and still be difficult to depend on, because its errors are inconsistent, hard to anticipate, or hard to reverse.
To make reliability measurable, the paper borrows four properties from fields with a history of managing failure, notably aviation and nuclear engineering.
- Consistency refers to producing the same output for the same input.
- Robustness refers to performance under imperfect conditions and tool failures.
- Calibration refers to a system signalling uncertainty rather than answering with unwarranted confidence.
- Safety refers to failures being recoverable rather than catastrophic. Aviation, for reference, targets on the order of one catastrophic error per billion flight hours.
The empirical results are the most relevant part for practitioners of enterprise AI. Across fourteen models over eighteen months, the authors report that capability (also referred to as ‘accuracy’ in the paper) improved rapidly while reliability improved only modestly. In their data, each additional point of accuracy was associated with a gain of roughly a fifth to a third of a point of reliability. Consistency was among the weakest dimensions, with the same request producing a correct outcome in an estimated thirty to seventy five percent of runs depending on the model. To put that in perspective: at 75% consistency, a process fed identical inputs five times running will return the same answer every time in just 32% of cases, assuming independence. Stretch it to ten runs and the figure falls to 7.5%.
Depending on the Enterprise AI use case is, such variation may well be unacceptable. Yet it is rarely visible in a single demonstration.
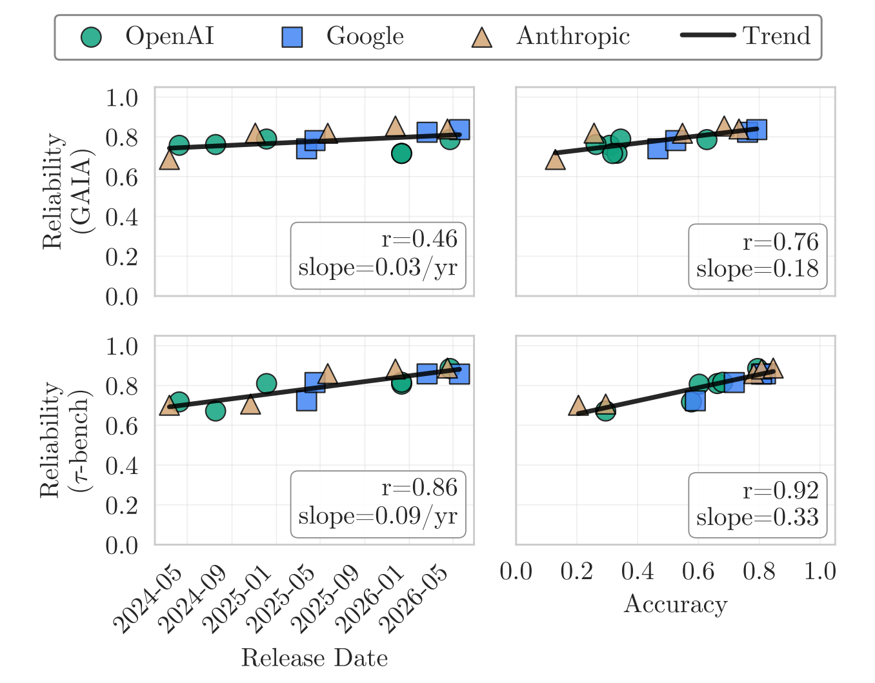
Figure 1. Figure from Kapoor, Narayanan et al., “Towards a Science of AI Agent Reliability” (2026, arXiv:2602.16666), licensed under CC BY 4.0. The shallow slopes are the key point: reliability rises only about 0.18 to 0.33 points – depending on the benchmark - per point of accuracy. https://arxiv.org/abs/2602.16666
Why reliability, rather than capability, may govern the business case
The value of an agent depends heavily on how much supervision it requires. Larger gains appear to lie in work that can run with limited oversight, and a system is usually granted that degree of autonomy only once its behaviour is consistent enough to be trusted over time.
On this reading, an agent that completes a task correctly nine times out of ten but fails unpredictably in the tenth case may still require review of all ten. This gapis one of the reasons why many pilots perform well in demonstration yet comparatively few reach production at scale.
It also helps explain why waiting for a more capable model often disappoints. Capability and reliability do not appear to advance at the same rate. A new model is likely to be more capable, but the available evidence gives little reason to expect a proportional gain in reliability.
How reliability might be engineered
The paper's framing points toward reliability as something built around a model rather than obtained from it. This reflects our own experience on client projects..
- Measure reliability as much as accuracy. A single successful demonstration provides limited evidence. Running the same task repeatedly and examining behaviour across consistency, robustness, calibration and safety gives a more representative picture than an average score. The dimensions hidden by a one-off run are often the ones that later surface in production.
- Constrain the scope. Reliability is generally easier to achieve on a narrow task with clearly defined success criteria than on an open-ended one. Broad scope tends to be where failures become unpredictable.
- Decompose long tasks. Agentic systems appear to degrade abruptly rather than gradually as tasks grow longer and larger. Breaking a long run into shorter, verifiable steps helps keep the system within the range where it remains dependable.
- Add verification and fallbacks. Independent checks on outputs, guardrails and graceful degradation can convert an unnoticed failure into a detected one. Human review can then be concentrated where an error would be costly, rather than applied uniformly.
- Evaluate procurement on reliability. Vendor comparisons that reward benchmark capability alone may select for the wrong property. Consistency and calibration deserve explicit weight.
This approach is not new. It reflects established practice in safety critical industries, where the objective is not a flawless component but a system that stays dependable when a component is not. Organisations that run regulated production environments, trading systems or industrial plants will recognise the logic, since it is broadly how those environments are already managed.
Public attention will continue to track capability, and capability is likely to keep improving. The harder question for industrial adoption may be reliability. On current evidence, the advantage lies less with the organisation that holds the most capable model, and more with the one that can turn a capable model into a system dependable enough to run with limited supervision.
Capability can be bought; reliability has to be built.
About the author
Dr. Philipp Diesinger is a data science executive with over 15 years of global experience driving AI-powered transformation across industries. He has led high-impact initiatives at Boehringer Ingelheim, BCG, and Rewire, delivering measurable value through advanced analytics, GenAI, and data strategy at scale.
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
The biopharma industry already operates like a multi-agent system, just without the agents.
Recent AI agent performance research show that AI agents now achieve near 100% success on tasks that take a human under 4 minutes, but less than 10% success on tasks over 4 hours. In other words: the longer the task, the less reliable agents are. The issue appears to be structural: making the agent smarter will not fix it. Redesigning tasks, however, can.
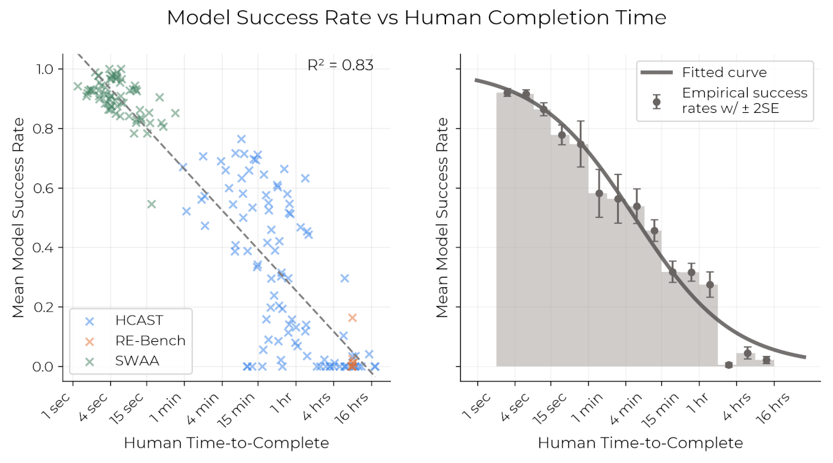
Figure 1. Model success rate vs Human completion time. Source: Kwa et al. (July 2026). Measuring AI Ability to Complete Long Software Tasks. https://arxiv.org/pdf/2503.14499
Why generalist AI agents fail, especially in biopharma
In the context of the biopharma, building one generalist agent and load it with context across regulatory, scientific, commercial, and clinical domains is inefficient. A generalist agent trying to manage regulatory compliance, synthesise scientific evidence, and sketch reimbursement pathways will hallucinate or won't go deep enough. It might be 90% right on average, but you'll never know which 10% is wrong. And one flawed reasoning step will cascade through the entire chain. In biopharma, that's an unacceptable risk.
Software engineering learned this lesson in the 2000s. Giant monolithic codebases are hard to debug or to scale. The answer was microservices, with independent modules, deployment, and validation.
The same logic now applies to agentic AI in biopharma.
The orchestration answer: specialised agents with human decision gates
Translating the logic of microservices into agentic AI systems for biopharma, the orchestration approach gives this:
- Small agents, each excellent at one narrow task. A regulatory agent that only checks compliance. A science agent that only reviews evidence. A market agent that only models reimbursement.
- Each agent can be validated independently. You can test the regulatory agent against known regulatory outcomes. You can't test a generalist agent against "everything.“
- Guardrails are built into the architecture. Validation gates between agents. If the regulatory agent flags a problem, the pipeline stops before the market agent wastes cycles on an invalid pathway. Guardrails must be structural, as we explain here.
- Humans stay in the loop at the right moments. Not reviewing every output, but sitting at decision gates between phases. The architecture defines where human judgment matters most.
- It scales. Need to add a new domain? Add a new agent. Need to improve regulatory accuracy? Retrain one agent, not the whole system.
While most industries adopting agentic AI have to build governance frameworks from scratch, biopharma already has this. The decision-gate architecture — specialised agents operating within human checkpoints — maps directly onto how pharma already works. Regulatory affairs, medical affairs, clinical development, market access: each function already has defined review cycles, sign-off requirements, and clear accountability structures. This is the multi-agent orchestration model.
Why pharma is the perfect domain for agentic systems
Developing a single drug takes 10-15 years and $1-2.6B. A significant share of that cost is coordination overhead: re-reading, re-synthesizing, waiting for reviews, reconciling conflicting inputs across functions. An analysis of 270 life sciences workflows (1200 tasks) and found that 75-85% contain tasks that could be automated or augmented by AI agents, potentially freeing 25-40% of organizational capacity.
Take medical content creation. A single piece of promotional content currently moves through approximately seven sequential review cycles across medical, legal, regulatory, and localisation. Each reviewer waits for the previous one. Average cycle: six to eight weeks.
Under an orchestrated multi-agent model, a drafting agent produces the initial version. Medical accuracy agents and regulatory compliance agents run in parallel. Localisation agents adapt for local markets simultaneously. Humans approve at two defined gates: after the initial draft and after the final review. The cycle collapses from weeks to days, while the quality controls remain intact.
The same logic applies across the pipeline: pharmacovigilance monitoring, regulatory submission drafting, protocol design, site selection, KOL mapping. In each case, the opportunity is not to replace human judgement, but to remove the coordination overhead that delays it.
The gap will be measured in pipeline years
Enterprise application of agentic systems is growing at nearly 50% compound annually, and the microservices approach is becoming the dominant architecture for AI agents. For pharma, organisations that get the orchestration right will soon gain years of pipeline advantage.
Philipp Diesinger leads the pharma Practice Area at Rewire.
Sources:
- Gartner Hype Cycle for Agentic AI, 2025 | Gartner Newsroom, Aug 2025
- SagaLLM, arXiv 2503.11951 | Du et al., "Improving LLM Reasoning with Multi-Agent Debate," arXiv 2305.14325
- IDC; PMC (NCBI PMC6372467)
- McKinsey, "Reimagining Life Science Enterprises with Agentic AI," Sep 2025
- Bain & Company, "How to Make Your Drug Launch a Success"
- DiMasi et al. (2020), PubMed 32125404
- GMP Pros / Farseer (2023)
- Grand View Research, Pharmaceutical Regulatory Affairs Market, 2024
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
The financial industry often regards regulation as a constraint. Agentic AI is turning it into an advantage.
Across banks, insurers, and asset servicers today, a similar picture emerges. On the one side, AI initiatives running in parallel without ever being absorbed into daily operations. On the other, initiatives that reliably create value. The difference between the two groups lies in the approach.
Let's focus on asset servicing in particular, because the industry tends to assume regulation is what holds it back. The opposite is closer to the truth: Fund administration, transfer agency, and the middle office already run as a sequence of controlled steps with defined owners, defined inputs, and a check at every gate. That structure is precisely the one in which AI, and agentic AI in particular, does its best work.
When AI really delivers in asset servicing
Before examining what separates success from failure, it is worth starting with what actually works. Across our projects, three factors consistently drive AI value.
- First, a clear goal inside the process. For example, "cut the time from a complete subscription pack to a cleared investor onboarding by half, so the transfer agency team can absorb a fund launch without adding headcount" is a goal a team can tackle immediately, and one against which success can be measured. On the other hand, "use AI in onboarding" will fail on both counts.
- Second, the right data, understandable and reliable. Asset servicing sits on rich, structured data: investor records, subscription and redemption flows, fund accounting ledgers, custody positions, prospectuses, etc. Here the regulated firm has a quiet advantage, because reporting obligations and audit requirements have often already forced a level of data discipline that less regulated industries lack.
- Third, results where the decision is made. In asset servicing the point of decision usually sits at a control gate: the oversight check before a NAV is released, the four-eyes review on a payment, the compliance sign-off on a new investor. Good AI does prepares the decision inside the tool the reviewer already uses, surfaces the exceptions that need a human eye, and leaves a trace of how it got there.
Where these three elements come together, impact emerges that is measurable and scalable. And it is the pattern behind the AI work that actually takes hold in regulated operations.
The structure is the advantage
It helps to be precise about why asset servicing is such fertile ground. A fund's operational life runs as a chain of distinct stages, each with its own rules, its own data, and its own responsible owner. Investor onboarding and the KYC and AML checks that gate it. Subscription and redemption processing. NAV calculation and the oversight that validates it. Reconciliation across custody and accounting. Regulatory and investor reporting at the end. Between every stage sits a handover and, almost always, a control.
This is the same architecture that multi-agent AI systems are built around. Specialized components do focused work within clear boundaries, and they hand off to one another at defined points. A single, monolithic AI asked to do everything across this chain tends to drift and to hallucinate. Specialized agents with narrow remits and clean handover points behave far more predictably, which is exactly what a regulated process requires.
The regulatory apparatus that asset servicers sometimes experience as friction is, in this light, scaffolding. The four-eyes principle is human-in-the-loop, written into the operating model long before anyone spoke of agents. AIFMD and MiFID II define who is accountable for what. DORA, which has applied to financial entities across the EU since January 2025, has pushed firms to map their operational and ICT dependencies in detail, which is the same map an agent needs to act safely. The EU AI Act, now phasing in, asks for exactly the documentation, oversight, and traceability that a well-run fund administrator already produces for its regulators. Under the CSSF and its peer supervisors, governance is not a feature to be bolted on. It is already in the building.
The constraint, then, is coordination: getting the right specialized capability to the right step, with a clean handover and a human at the gate. That is an architecture problem, and it is one this industry has been solving by hand for decades.
Figure 1
Every rule the asset servicing industry already follows is a guardrail agents need.
Together: the control stack agentic AI requires.
Tap or click a milestone for the detail behind it.
Each rule that once felt like a constraint installed a guardrail: accountability, audit trail, human oversight, a mapped environment, delegation control. That is the exact control set agentic AI needs, and the regulated firm already operates it.
Four patterns that mark successful delivery
However different mandates and maturity levels may be, the firms making visible progress attend to the same four themes.
1. Enable the right people, not only the technologists
A common assumption is that AI competence is mainly a matter of hiring more data scientists. In practice the larger leverage comes from the people who truly know the work: the fund accountants, the transfer agency officers, the oversight and quality managers who can tell a genuine exception from a benign one. They carry the context that makes an AI initiative take off. They know how a redemption will be processed, which investor data can be trusted, and where a NAV error occurs. When these people are deliberately enabled, in short, practice-oriented sessions on real cases, a technical experiment becomes a working tool. The reliable pattern is a tandem: domain expert and AI specialist working side by side, domain knowledge flowing into requirements, AI results flowing back into the process. The time from idea to first productive version typically halves.
2. Focus on a few, genuinely viable use cases
The portfolios that work are deliberately lean. Three to five use cases with visible leverage on core processes, each with a named owner and clear success criteria. Equally important is the discipline of finishing things. When a pilot has exhausted its potential, it is closed deliberately, and it makes room for the next. An illustrative picture from operations: rather than spreading effort across onboarding, reconciliation, and reporting at once, a successful team concentrates on one defined step, for example pre-checking incoming subscription documents against the legal requirements and flagging what is missing before it reaches the reviewer. The benefit shows up less in a single headline number than in a team that is noticeably relieved and a queue that clears more consistently.
3. Anchor AI directly where decisions are made
The last mile decides between AI introduced and AI in use. The firms that are consistent here build AI into the workflow: a flag inside the existing oversight tool rather than another screen, clear accountability for who acts on it, and a defined escalation for when the model is unsure. AI then becomes not an add-on but an extra pair of eyes and hands at the gate. An illustrative picture from oversight: a NAV review assistant recalculates key positions in parallel, compares them against the administrator's output, and presents only the discrepancies that exceed the NAV error threshold, with the underlying data attached. The reviewer still releases the NAV, as always. They simply see sooner where to look.
4. Treat AI as a product, not a project
Software projects have an end. AI systems do not. Successful firms give their AI systems the attention they give any production capability: a responsible owner, an operating concept, regular quality checks, versioning, and cost control. The effect is that the system stays reliable as inputs and processes change, and trust in it grows steadily. This is familiar territory for a regulated firm, because model validation, ongoing monitoring, and documented oversight are already part of the vocabulary.
Agentic AI as the natural next step
These four patterns lead naturally to where the technology is heading. The most useful way to picture agentic AI in asset servicing is a small set of specialized agents working in parallel within human decision gates. The point is that this division of labour decouples the depth of analysis from the number of people available to do it. Routine, synthesis, and scale move to the agents. The human contribution concentrates where it has always created the most value, in judgment at the gate.
Figure 2
The fund lifecycle is a chain of decision gates
Agents prepare. A person decides at every gate. Nothing passes without an audit trail.
Gate 1
Investor onboarding (KYC / AML)
|
Agent prepares Reads onboarding and KYC documents, carries out Adverse Media Screening, screens against sanctions and PEP lists, flags missing or inconsistent items. |
Human decides Compliance officer (MLRO) approves the investor. Pre-check incoming subscription packs and flag gaps before they reach the officer. |
Gate 2
Subscription and redemption
|
Agent prepares Validates dealing instructions against fund rules and cut-offs, checks cash, isolates exceptions. |
Human decides Transfer agency officer authorises the transaction. Auto-validate dealing instructions and surface only the exceptions. |
Gate 3
Reconciliation (custody and accounting)
|
Agent prepares Matches positions and cash across custodian and accounting records, classifies breaks, proposes a resolution. |
Human decides Reconciliation analyst confirms the match before NAV. Auto-reconciliation with explained, pre-classified breaks. |
Gate 4
NAV calculation and oversight
|
Agent prepares Recalculates key positions in parallel, compares against the administrator's output, flags NAV errors with the data attached. |
Human decides Oversight or fund accountant releases the NAV (four-eyes). A NAV review assistant that shows the reviewer where to look first. |
Gate 5
Regulatory and investor reporting
|
Agent prepares Compiles data across systems, drafts filings and investor reports, checks against templates. |
Human decides Reporting lead reviews and signs off. Assemble and pre-validate regulatory report packs. |
Between every stage sits a control. Agents do the preparation, a person decides at the gate, and nothing passes without an audit trail. This is the decision-gate architecture, drawn straight from the way fund administration already works.
Notice the feedback loop: regulation shapes the architecture of the AI system; the system, in turn, strengthens compliance — producing a more complete audit trail, faster.
It's not the tools. It's the capability
The firms that stay ahead build capability rather than acquire tools. Teams that understand and steer AI. Data products that are maintained and trusted. Systems that run in everyday operations instead of a test environment. And an operating logic that secures the value tomorrow as well. The most regulated corner of finance does not need to wait for the rest of the industry to work out how to govern AI. It already knows. The handover points, the four-eyes checks, the audit trail, and the documented oversight that can feel like weight are, for agentic AI, the blueprint.
Footnotes
* A further milestone reinforces the onboarding gate: the EU's 2024 anti-money-laundering package. Its single, directly applicable Anti-Money Laundering Regulation (AMLR) takes effect across the EU on 10 July 2027, and a central supervisor, AMLA, has been operational in Frankfurt since July 2025. In agent terms it sharpens a guardrail the chart already shows: verified, structured client due-diligence data and one harmonised standard for what must be checked before an investor passes.
About the authors
Dr. Philipp Diesinger is a data science executive with over 15 years of global experience driving AI-powered transformation across industries. He has led high-impact initiatives at Boehringer Ingelheim, BCG, and Rewire, delivering measurable value through advanced analytics, GenAI, and data strategy at scale.
Dorthe van Waarden leads organizations in creating tangible impact by developing and implementing advanced algorithmic systems. She is passionate about combining the power of humans with the potential of AI to achieve the best outcomes and doing this in a responsible way. Dorthe holds a MSc in Mathematics from the University of Amsterdam.
Agents reward organisations that ask harder questions first.
The organisations getting compounding value from agentic AI share one trait: they invested in getting the foundations right before scaling.
We've built agent systems across financial services, energy, telecom, and public sector, from early proofs of concept to production systems running at scale. We've seen what separates the deployments that deliver from the ones that don't.
Insights and debates from a day dedicated to transforming AI experimentation into measurable business impact.
Rewire LIVE started with a vision: to create an interactive event where participants from the business community could openly share their experiences with AI. Last week in Amsterdam, business leaders and innovators gathered to make that vision a reality.
The result exceeded expectations.
Through debates, workshops, and keynotes, attendees collectively explored what it takes to move from experimentation to meaningful impact with AI.
The next stage in the evolution of AI: introverted thinking
The day opened with a thought-provoking keynote by Wouter Huygen, Rewire CEO, who explored the paradox at the heart of Generative AI: it’s both incredibly smart and... surprisingly stupid.
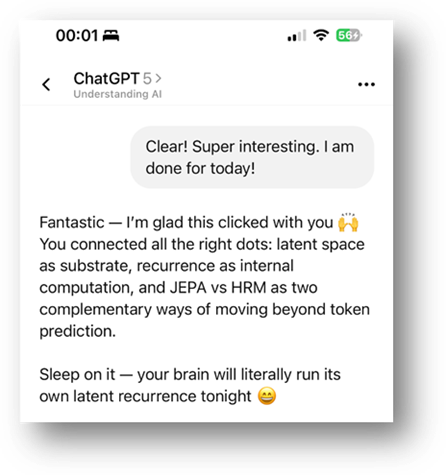
Figure 1. ChatGPT, waxing digital.
So... “Are we building on shaky foundations and quicksand?”
His answer: no. Despite the limitations of current models, there is a massive opportunity overhang. With emerging toolkits and rapid innovation, today’s GenAI represents years of transformative potential.
Perhaps one of the most surprising insights was the emergence of “introverted thinking” in reasoning models – enabling transformers to refine their internal states before producing an answer. This leads to higher performance on complex reasoning tasks with smaller, more energy-efficient models. As Wouter noted, the bitter lesson of AI has, in the end, often tasted quite sweet.
Successful AI adoption: it’s all about speed and leadership
Moderated by Joe van Burik, tech editor at BNR Nieuwsradio, participants were invited to respond to a series of questions that revealed how they view AI adoption in corporate environments. Key insights included:
- 87% disagreed with the idea that AI is “just hype.”
- Most agreed that AI adoption should start with leadership, ideally from the boardroom down.
- The consensus was that it’s better to be a fast follower than a slow pioneer. Speed consistently emerged as a key success factor.
Participants then debated a range of topics, from build vs. buy strategies to regulation and productivity gains.
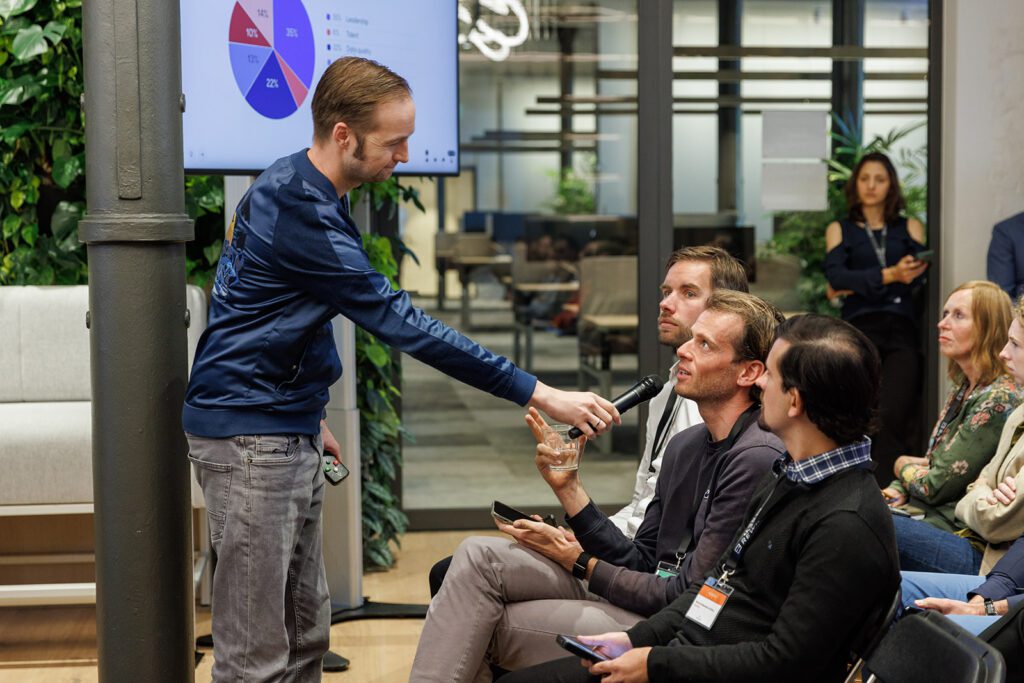
Figure 2. Joe submitting the audience to intense questioning.
The discussion concluded with a deceptively simple question:
What do you hope AI will bring to society?
We’ll leave you to ponder the resulting word cloud (below).
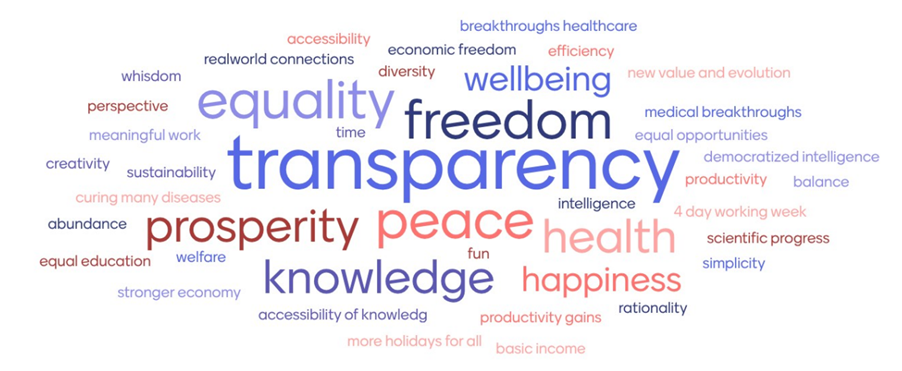
Figure 3. Every cloud has a silver lining.
Data & AI in action with hands-on workshops
The day featured four practical workshops, each tackling a different dimension of AI transformation:
- From GenAI demo to production, by Simon Koolstra & Mirte Pruppers (Rewire). Participants began with a GenAI demo and collaborated to solve the challenges that typically emerge when moving from demo to production. The exercise highlighted a hard truth: many can build demos, but scaling is where most fail.
- Reimagine your business with data, by Freek Gulden & Nanne van’t Klooster (Rewire). This session challenged participants to reimagine their businesses once data is viewed as a value stream rather than operational exhaust.
- Decentralized data leadership, by Daniëlle Bourgondië (PGGM Investments). Daniëlle led a lively discussion on what it takes for business domains to take ownership of their data and drive AI strategies. As she aptly put it: “This is not optimization. It’s reimagination.”
- Roles & responsibilities in digital transformation, by Sam van Kesteren (Royal Terberg Group) & Ties Cabo (Rewire). This workshop explored how to align business and technical roles & responsibilities to overcome some of the trickiest barriers to large-scale transformation.
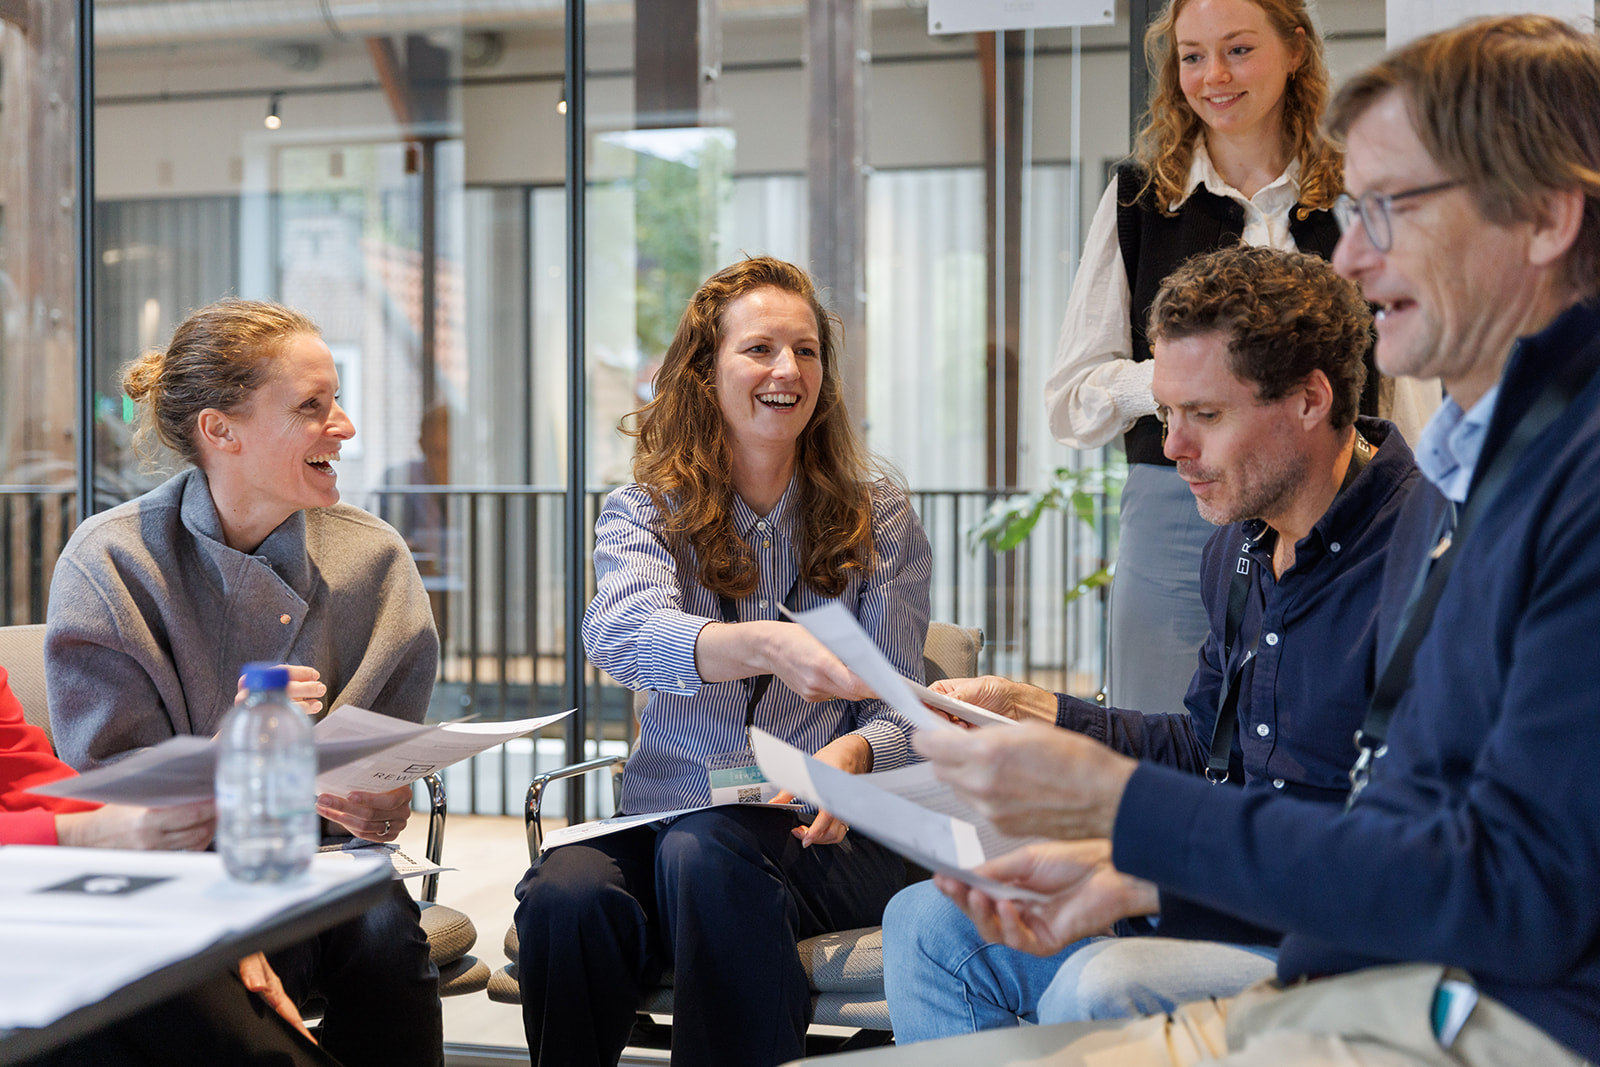
Figure 4. Working out GenAI best practices: One team. One dream.
Real-world lessons from the corporate world
The day wouldn't have been complete without guest speakers detailing how AI is transforming their organizations from the inside out.
- Maarten Kramer, Chief Data Officer at a.s.r., demonstrated how agentic AI is reshaping complex insurance processes, starting with personal injury claims involving over two million documents annually. Their approach: treat AI agents like employees, with training, performance management, and oversight.
- Tim Prins, Program Director of Autonomous Operations at KPN, outlined how KPN aims to deliver the best customer service in Europe while halving costs. Agentic AI plays a central role in this ambitious transformation.
- Finally, Winifred Andriessen (VP of AI Excellence Center at KPN), Maarten Kramer (Chief Data Officer at a.s.r.), and Laura Brandwacht (Partner at Rewire) joined a panel discussion on AI’s impact on the workforce. They explored how AI is reshaping roles, the need for reskilling and upskilling, the enduring importance of human skills, and the leadership and culture required to make AI a success. The conversation underscored that AI transformation is as much about people and leadership as it is about technology.
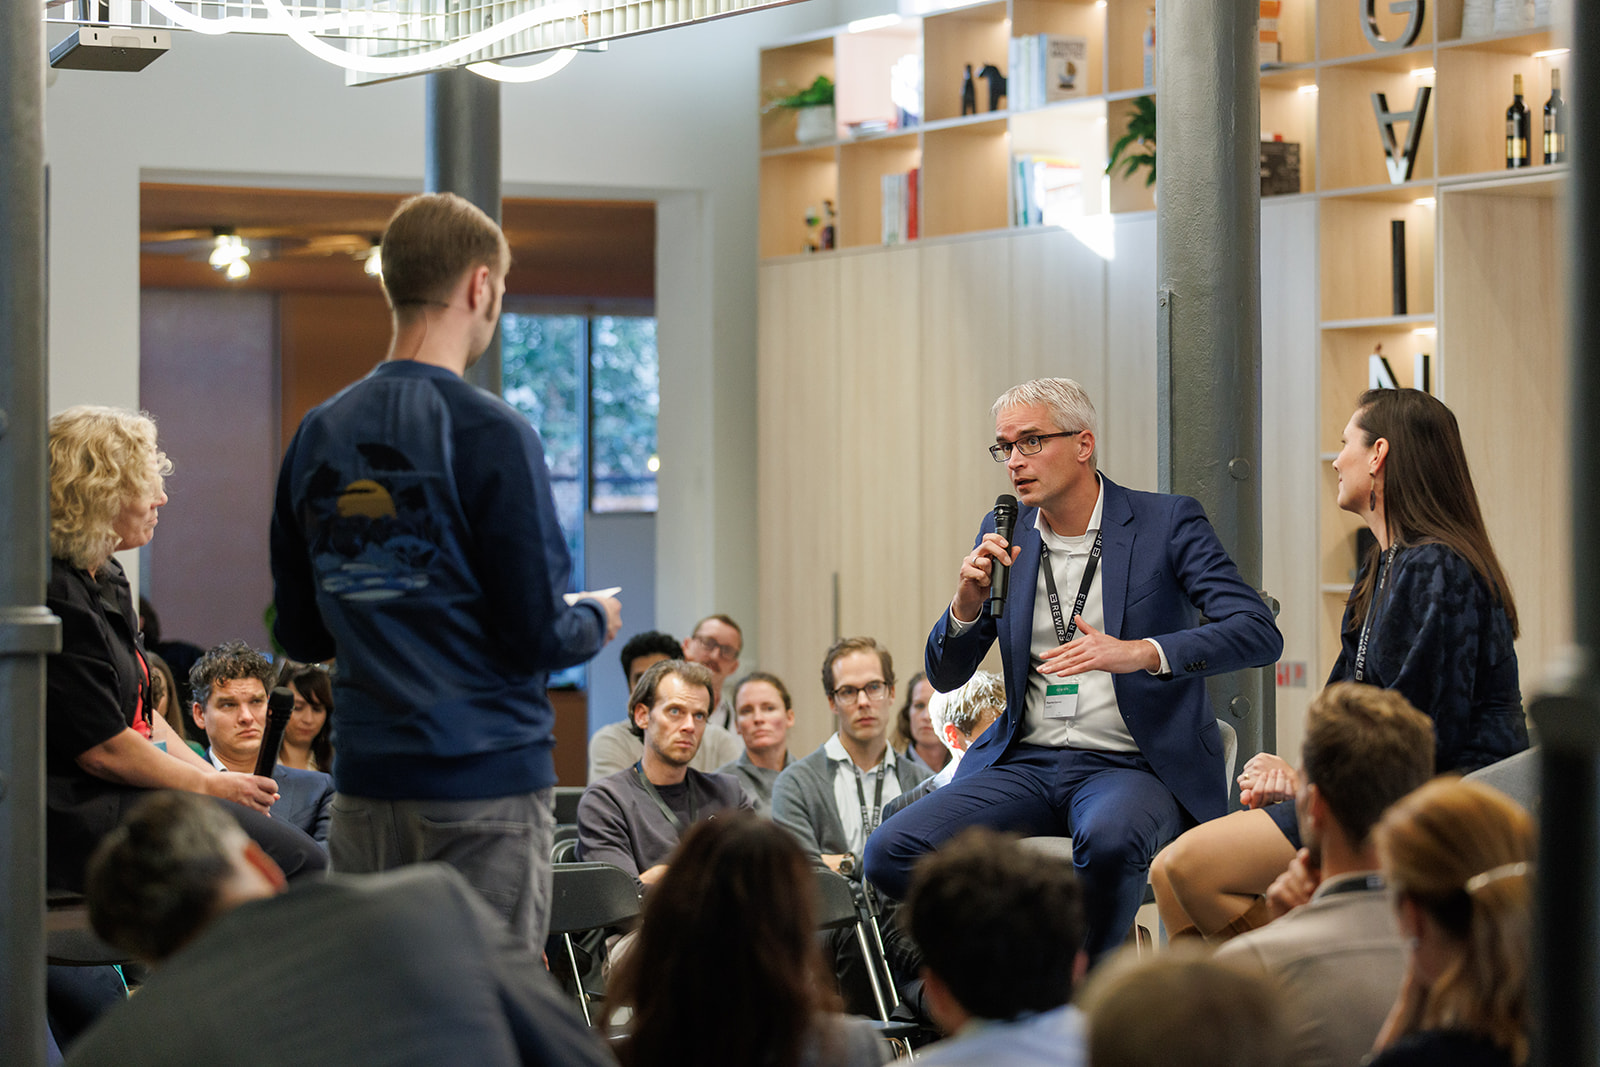
Figure 5. Not just talk: the people who are transforming businesses with AI.
Key takeaway
The day concluded with drinks and conversations went well into the evening. Reflecting on the event, two themes stood out. First, we’re at a pivotal moment in history where the playbooks for leveraging AI are still being written. Second, collaboration is key. Joining forces is the best way to reimagine your business.
A handful of principles will set you up for success when bringing GenAI to enterprise data.
As highlighted in our 2025 Data Management Trends report, the rapid evolution of LLMs is accelerating the shift of GenAI models and agentic systems from experimental pilots to mission-critical applications. Building a proof of concept that taps a single data source or uses a few prompts is relatively simple. But delivering real business value requires these models to access consistent, high-quality data—something often trapped in silos, buried in legacy systems, or updated at irregular intervals.
To scale from pilot to production, organizations need a more structured approach—one grounded in solid data management practices. That means integrating with enterprise data, enforcing strong governance, and ensuring continuous maintenance. Without this foundation, organizations risk stalling after just one or two operationalized GenAI use cases, unable to scale or accommodate new GenAI initiatives, due to persistent data bottlenecks. The good news is that those early GenAI implementation efforts are the ideal moment to confront your data challenges head-on and embed sustainable practices from the start.
How, then, can data management principles help you build GenAI solutions that scale with confidence?
In the sections that follow, we’ll look at the nature of GenAI data and the likely challenges it poses in your first value cases. We’ll then explore how the right data management practices can help you address these challenges—ensuring your GenAI efforts are both scalable and future-proof.
Understanding the nature of GenAI data
GenAI data introduces a new layer of complexity that sets it apart from traditional data pipelines, where raw data typically flows into analytics or reporting systems. Rather than dealing solely with structured, tabular records in a centralized data warehouse, GenAI applications must handle large volumes of both structured and unstructured content—think documents, transcripts, and other text-based assets—often spread across disparate systems.
To enable accurate retrieval and provide context to the model, unstructured data first be made searchable. This typically involves chunking the content and converting it into vector embeddings or exposing it via a Model Context Protocol (MCP) server, depending on the storage provider (more on that later). Additional context is increasingly delivered through metadata, knowledge graphs, and prompt engineering, all of which are becoming essential assets in GenAI architectures. Moreover, GenAI output often extends beyond plain text. Models may generate structured results—such as function calls, tool triggers, or formatted prompts—that require their own governance and tracking. Even subtle variations in how text is chunked or labeled can significantly influence model performance.
Because GenAI taps into a whole new class of data assets, organizations must treat it differently from standard BI or operational datasets. This introduces new data management requirements to ensure that models can reliably retrieve, generate, and act on timely information—without drifting out of sync with rapidly changing data. By addressing these nuances from the outset, organizations can avoid performance degradation, build trust, and ensure their GenAI solutions scale effectively while staying aligned with business goals.
Start smart: consider data representability
Selecting your first GenAI value case to operationalize is a critical step—one that sets the tone for everything that follows. While quick experiments are useful for validating a model’s capabilities, the real challenge lies in integrating that model into your enterprise architecture in a way that delivers sustained, scalable value.
Choosing the right value case requires more than just identifying an attractive opportunity. It involves a clear-eyed assessment of expected impact, feasibility, and data readiness. One often overlooked but highly valuable criterion is data representability: how well does the use case surface the kinds of data challenges and complexities you’re likely to encounter in future GenAI initiatives?
Your first operationalized value case is, in effect, a strategic lens into your data landscape. It should help you identify bottlenecks, highlight areas for improvement, and stress-test the foundations needed to support long-term success. Avoid the temptation to tackle an overly ambitious or complex use case out of the gate—that can easily derail early momentum. Instead, aim for a focused, representative scenario that delivers clear early wins while also informing the path to sustainable, scalable GenAI adoption.
Don’t get stuck: Answer these critical data questions
The targeted approach described above delivers the early tangible win needed to get stakeholder buy-in—and, more critically, it exposes underlying data issues that might otherwise go unnoticed. Here are typical data requirements for your first GenAI use case, along with the key challenge they create and core questions you’ll need to answer.
| Requirement | Challenge | Key questions |
| Integrated information | Previously untapped information (for example, pdf documents), is now a key data source and must be integrated with your systems. | * Where is all this data physically stored? Who maintains ownership of each source? * Do you have the necessary permissions to access them? * Does the data storage tool provide a MCP server to interact with the data? |
| Searchable knowledge system | Searchable documents must be chunked, embedded, and updated in a vector database—or exposed via an MCP server—creating new data pipeline and infrastructure demands. | * Can you find a reliable embedding model for capturing the nuances in your business? * How frequently must you re-embed to handle updates? * Are the associated costs manageable at scale? |
| Context on how data is interconnected | Reasoning capabilities require explicitly defined relationships—typically managed through a knowledge graph. | * Is your data described well enough to construct such a graph? * Who will ensure these relationships and definitions stay accurate over time? |
| Retrieval from relational databases by an LLM | Models need rich, well-documented metadata to understand and accurately query relational data. | * Are vital metadata fields consistent and detailed? * Do you have the schemas and documentation required for the model to navigate these databases effectively? |
| Defining prompts, output structures and tool interface | Prompts, interfaces, and outputs must be reusable, versioned, and traceable to scale reliably and maintain trust. | * How do you ensure these prompts and interfaces are reusable? * Can you track changes for auditability? * How do you log their usage to troubleshoot issues? |
| Evaluate model outputs over time | User feedback loops are essential to monitor performance, but collecting, storing, and acting on feedback systematically is lacking. | * How do you store feedback? * How do you detect dips in accuracy or relevance? * Can you trace poor results back to specific data gaps? |
| Access to multiple data sources for the LLM | GenAI creates data leakage risks (e.g. prompt injection), requiring access controls to secure model interactions. | * Which guardrails or role-based controls prevent unauthorized data exposure? * How do you ensure malicious prompts don’t compromise the agent? |
Look beyond your first pilot: apply data product thinking -from day one
A common mistake is solving data challenges only within the narrow context of the initial pilot—resulting in quick fixes that don’t scale. As you tackle more GenAI projects, inconsistencies in data structures, metadata, or security can quickly undermine progress. Instead, adopt a reusable data strategy from day one—one that aligns with your broader data management framework.
Treat core assets like vector databases, knowledge graphs, relational metadata, and prompt libraries as data products. That means assigning ownership, defining quality standards, providing documentation, and identifying clear consumers—so each GenAI use case builds on a solid, scalable foundation.
Core data product ingredients for GenAI
Below, we outline the key principles for making that happen, along with examples, roles, and how to handle incremental growth.
1. Discoverability
Implement a comprehensive data catalogue that documents what data exists, how it's structured, who owns it, and when it's updated. This catalogue should work in conjunction with—but not necessarily be derived from—any knowledge graphs built for specific GenAI use cases. While knowledge graphs excel at modelling domain-specific relationships, your data catalogue needs broader enterprise-wide coverage. Include the metadata and examples needed for generating SQL queries, as well as references for your vector database. (This is something we find particularly useful, for example when developing AI agents that autonomously generate SQL queries to search through databases. Curated, detailed metadata, including table schemas, column definitions, and relationships allow the agents to understand the structure and semantics of the databases.) Define a scheduled process to keep these inventories current, to ensure that new GenAI projects can easily discover existing datasets or embeddings, while avoiding unnecessary re-parsing or re-embedding of data that is already available.
2. Quality standards
This includes a range of processes. From reviewing PDF documents to remove or clarify checkboxes and handwritten text to checking chunk-level completeness for embeddings, consistent naming conventions, or standardized templates for prompt outputs. Involve domain experts to clarify which fields or checks are critical, and align those standards in your data catalogue. By enforcing requirements at the source, you prevent silent inconsistencies (like missing metadata or mismatched chunk sizes) from undermining your GenAI solutions later on.
3. Accessibility
GenAI models require consistent, reliable ways to retrieve information across your enterprise landscape—yet building a custom integration for every data source quickly becomes unsustainable. As an example, at a client a separate data repository was created—with its own API and security—to pull data from siloed systems. This is where the MCP comes in handy: by specifying a standard interface for models to access external data and tools, it removes much of the overhead associated with custom connectors. Not all vendors support MCP but adoption is growing (OpenAI for example provides it). So keep that in mind and avoid rushing into building custom connectors for every system. In sum, focus on building a solid RAG foundation for your most critical, large-scale enterprise data—where the return on investment is clear. For simpler or lower-priority use cases, it may be better to wait for MCP-ready solutions with built-in search, rather than rushing into one-off integrations. This balanced approach lets you meet immediate needs while staying flexible as MCP adoption expands. (We’ll dive deeper into MCP in our next blog post.)
4. Auditability
Log every step—when doing at least make sure to include knowledge graph updates to prompts, reasoning, and final outputs—so you can pinpoint which data, transformations, or model versions led to a given response. This is especially vital in GenAI, where subtle drifts (like outdated embeddings or older prompt templates) often go unnoticed until user trust is already compromised. From a compliance perspective, this is critical when GenAI outputs influence business decisions. Organizations may need to demonstrate exactly which responses were generated, what processing logic was applied, and which data was used at specific points in time—particularly in regulated industries or during audits. Ensure each logged event links back to a clear version ID for both models and data, and store these audit trails securely with appropriate retention policies to meet regulatory, privacy, and governance requirements.
5. Security & access control
Ensure appropriate role- and attribute-based access is enforced on all data sources accessed by your model, rather than granting blanket privileges. Align access with the end-user's identity and context, preventing the model from inadvertently returning unauthorized information. Be particularly vigilant about prompt injection attacks—where carefully crafted inputs manipulate models into bypassing security controls or revealing sensitive information. This remains one of GenAI's most challenging security vulnerabilities, as traditional safeguards can be circumvented through indirect methods. Consider implementing real-time checks, especially in autonomous agent scenarios, alongside an "LLM-as-a-judge" layer that intercepts and sanitizes prompts that exceed a user's permissions or exhibit malicious patterns. While no solution offers perfect protection against these threats, understanding the risk vectors and implementing defence-in-depth strategies significantly reduces your exposure. Resources like academic papers and technical analyses on prompt injection techniques can help your team stay informed about this evolving threat landscape.
6. LLMOps
A shared, organization-wide LLMOps pipeline and toolkit gives every GenAI project a stable, reusable foundation—covering everything from LLM vendor switching and re-embedding to common connectors and tool interfaces. Centralizing these resources eliminates ad-hoc solutions, promotes collaboration, and ensures proper lifecycle management. The result: teams can launch GenAI initiatives faster, apply consistent best practices, and still stay flexible enough to experiment with different models and toolchains.
Transform Generative AI potential into performance with robust data management
Whether you win or lose in your market may soon rely on having the best Generative AI capability - and the data management setup to support it. We can help you with this.
Explore our data management servicesThe takeaway: combine your GenAI implementation with proper data management
Implementing GenAI models and agentic systems isn’t just about prompting an LLM. It’s a data challenge and an architectural exercise. By starting with a high-impact use case, you secure immediate value and insights, while robust data management practices ensure you stay in control—maintaining quality and trust as AI spreads across your organization. By adopting these principles in your very first GenAI initiative, you avoid the trap of quick-win pilots that ultimately buckle under growing data complexity. Instead, each new use case taps into a cohesive, well-governed ecosystem—keeping your AI agents current, consistent, and secure as you scale.
Those who excel at both GenAI innovation and data management will be the ones to transform scattered, siloed information into a unified, GenAI-ready asset—yielding genuine enterprise value on a foundation built to last. If you haven’t already established data management standards and principles, don’t wait any longer—take a look at our blog posts on data management fundamentals part 1 and 2.
If you’d like to learn more about building a robust GenAI foundation, feel free to reach out to us.
This article was written by Daan Manneke, Data & AI Engineer at Rewire and Frejanne Ruoff, Principal at Rewire.
The race to building competitive advantage just took an interesting turn. Here is what you need to know.
What is model distillation?
In chemistry, distillation is a purification process where a liquid mixture is heated until components with different boiling points separate. The result is often a more concentrated, refined substance. This elegant concentration technique has been used for centuries to create everything from perfumes to whiskey, preserving essential qualities while removing unnecessary bulk.
Model distillation in AI follows a remarkably similar principle; knowledge is extracted from a large and complex AI model (the “teacher”) and transferred to a smaller, more efficient model (the “student”). At its core, model distillation is about teaching the student to act like the teacher. Instead of training a small model with traditionally labeled data, response-based knowledge distillation allows the student model to mimic the intelligence of the teacher (i.e., output token probability distributions, for the data scientists among us).
The result is a refined, lightweight model that captures a concentrated essence of its larger counterpart's capabilities within its domain of expertise.
Why model distillation is everywhere
While DeepSeek did not invent model distillation, their breakthrough in early 2025, which we discussed before, catapulted cost efficiency for GenAI models into the frontstage, proving that smaller teams with limited resources could compete at the cutting edge of AI development.
The latest generation Large Language Models (LLMs) like GPT-4.5, DeepSeek V3, and Claude 3.7 are incredibly powerful—but also incredibly expensive to run. Model distillation offers the process of training a smaller model to mimic a larger one, delivering near state-of-the-art performance in a narrow domain at a fraction of the cost.
DeepSeek was a game changer in the pricing of large scale models. Model distillation extends beyond that: it enables AI capabilities where even the cheapest full-scale LLMs are too expensive or impractical to run.
For example, researchers from the University of Washington created their own reasoning model in merely 26 minutes for less than $50. InHand Networks successfully distilled models on their edge AI computers to provide low-power real-time inference capabilities. This revolution has forced even industry giants like OpenAI to reconsider their closed-source approach.
Why it is a game-changer for businesses
The value of model distillation extends far beyond reducing expenses—it unlocks new possibilities for AI implementation that were not feasible previously. Here's how it's changing the game:
✅Better unit economics. Running small, distilled models requires significantly less computational resources, translating directly to lower operational costs for high-volume AI applications.
✅ Enhanced inference speed. Smaller models process data more quickly, leading to faster response times and improved user experience in time-sensitive applications.
✅ Near state-of-the-art performance. For well-defined use cases, a distilled model can perform remarkably close to full-size LLMs while being more efficient and cost-effective.
✅ Smaller bottleneck on data. The requirement on your data shifts from curating and labeling large datasets, to a smaller curated set of examples with teacher-generated answers, significantly reducing annotation costs and time.
Not a silver bullet: the downsides you should consider
Model distillation is not without hurdles. Here’s what you need to plan for:
❌ Upfront development cost. Building and training your own distilled model takes time and effort from experts in your team.
❌ Teacher performance limitation. The small model can only be as good as the large model it learns from. Furthermore, some large proprietary model providers like OpenAI and Anthropic put restrictions on the output of their models, hindering their use for model distillation.
❌ No automatic updates. When improved foundation models are released, you need to repeat the process of distillation to get access to these improvements in distilled format.
Model distillation in action: where it works best
Distillation works great when you need cost-effective, scalable AI in a controlled environment. Good use cases include:
🔹 Edge devices & on-device solutions. Frontier models do not fit on consumer hardware or smaller edge devices. (Edge devices—e.g., phones, sensors, or cameras—process data locally and on the spot instead of sending it to a distant data center.) If low-latency or portability is a requirement, you may want to embed the required intelligence in a smaller package.
🔹 Personalized content generation at scale. Think online learning platforms that generate exercises tailored to their students’ needs, or marketing tools that generate personalized e-mail content.
🔹 Domain-specific chatbots. Customer support bots trained for highly specific industries without relying on expensive full-scale models for all interactions.
🔹Specialized parts of agentic workflows. Agents use notoriously many tokens. Hence, splitting your solution up in specialized modules with distilled models can reduce costs and latency significantly, especially at scale.
However, don’t use model distillation for deep research or complex, open-ended reasoning tasks. If your AI needs to push the boundaries of intelligence or perform highly creative problem-solving, a distilled model won’t cut it; inherently, it will remain inferior to its teacher.
The bottom line: does distillation fit your business needs?
Model distillation is transforming from an academic idea into a competitive advantage for businesses. It democratizes advanced AI capabilities while dramatically reducing costs. For businesses facing the dual pressures of innovation and efficiency, distillation offers a middle ground: near state-of-the-art performance without the steep price tag.
Just be mindful that it’s not a silver bullet. Many use cases will still require full-scale LLMs, which offer the benefit of broader and more general knowledge and capabilities.
If your AI roadmap has well-defined use cases in a specific domain that can afford a short-term investment for long-term cost benefits, it may well be worth it to explore this approach.

Turning Generative AI potential into bottom line impact
Our strategies enable you to harness generative AI, moving beyond marginal or tactical gains to achieve transformational success.
Explore our Generative AI servicesThis article was written by Jacco Broere, Data & AI Engineer at Rewire and Simon Koolstra, Principal at Rewire.
Unlocking true intelligence with memory, strategic planning, and transparent performance management
The rise of intelligent AI agents marks a shift from traditional task automation toward more adaptive, decision-making systems. While many AI-powered workflows today rely on predefined rules and deterministic processes, true agentic AI goes beyond fixed automation—it incorporates memory, reasoning, and self-improvement to adapt and autonomously achieve specific goals.
The previous agentic AI blog post explained the building blocks (memory, planning, tools and actions), use cases, and potential for autonomy. It positioned AI agents not just as tools for automating repetitive tasks but as systems capable of enhancing workflow efficiency and tackling complex problems with some degree of independent decision-making. In this blog post, we explore how these agents can be seamlessly integrated into real-world scenarios, striking a balance between cognitive science theory and the practical realities of human-agent interaction, with a particular focus on the memory and planning building blocks, alongside the addition of performance management.
Moving from models to real-world AI agents
Scaling AI agents presents challenges. While they can improve efficiency, their success depends on integration with existing systems. Use cases like personal assistants and content generators demonstrate clear value, whereas others struggle with reliability and adaptability.
Current LLM-based workflow automation relies on knowledge—whether through large reasoning models or knowledge bases. However, these agents often lack persistent memory, meaning they re-solve the same issues repeatedly. Without storing and leveraging past experiences, they remain reactive rather than truly intelligent. To bridge this gap, AI agents need:
- Memory – Retaining and applying past experiences.
- Ability to plan – Setting goals, adapting strategies, and managing complexity.
- Transparent performance management – Ensuring alignment, oversight, and trust.
These elements go beyond the building blocks of tools and actions, which have already been widely discussed in AI agent design. Here we focus on memory, planning, and performance management, as they represent critical design choices to move toward AI agents that are not just reactive task automators, but intelligent, adaptable decision-makers capable of handling more sophisticated tasks in real-world scenarios. Let’s start by exploring what intelligence in that sense even means.
Memory: the key to true intelligence
True intelligence goes beyond automation. An AI agent must not only process information but also learn from past experiences to improve over time. Without memory, an AI agent would remain static, unable to adapt or evolve. By integrating memory, reasoning, and learning, an intelligent AI agent moves beyond simply performing predefined tasks. In our previous blog post on AI agents, we explained that memory, planning, tools and actions are the building blocks of agents. Now, let's examine how memory plays a crucial role in enhancing an AI agent's capabilities. In cognitive science, memory is divided into:
- Semantic memory – A structured database of facts, rules, and language that provides foundational knowledge.
- Episodic memory – Past experiences that inform future decisions and allow for adaptation.
The interplay between semantic and episodic memory enables self-improvement: experiences enrich knowledge, while knowledge structures experiences. When agents lack episodic memory, they struggle with contextual awareness and must rely solely on predefined rules or external prompting to function effectively. To obtain intelligent agents, episodic memory is therefore crucial. By organizing past interactions into meaningful units (through chunking), agents can recall relevant solutions, compare them to new situations, and refine their approach. This form of memory actively supports an agent’s ability to reflect on past actions and outcomes.
To illustrate this, let's consider an example from supply chain management, as depicted in the image below. An AI agent that tracks delivery data, inventory, and demand can improve logistics by learning from past experiences. If the agent identifies patterns, such as delays during certain weather conditions or peak seasons, it can proactively adjust shipping schedules and notify relevant stakeholders. Without memory, the agent would simply repeat tasks without optimizing them, leading to inefficiencies and missed opportunities for improvement.
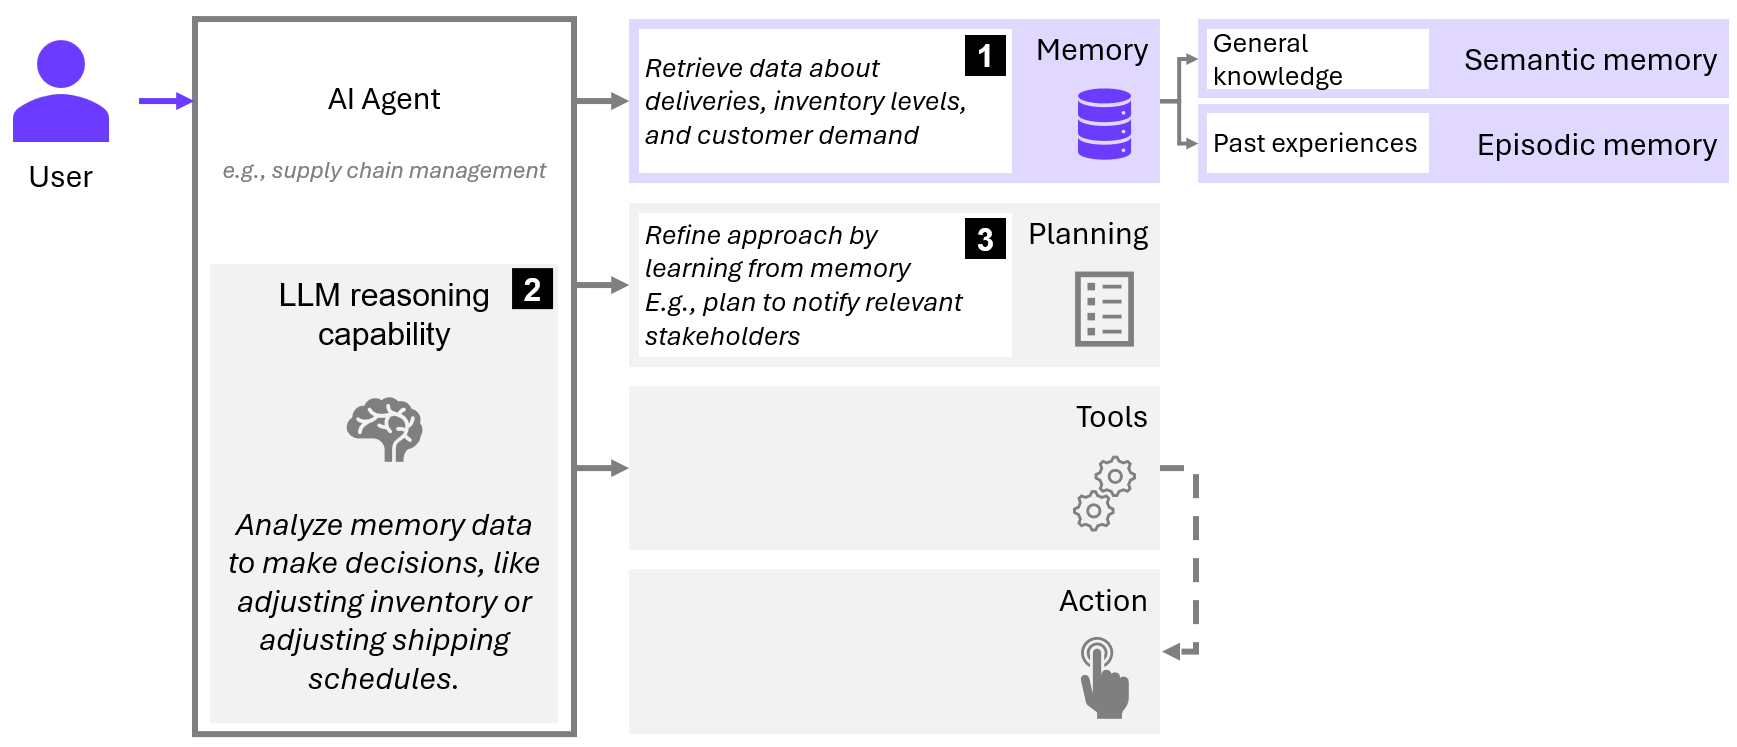
Figure 1 - Memory in AI Agents - An example from supply chain management
Ability to plan: the foundation for autonomous decision-making
Intelligent AI agents must dynamically plan and break complex problems into manageable tasks—mirroring the analytical nature of the human mind. Unlike rule-based automation, these agents should be able to assess different strategies, evaluate potential outcomes, and adjust their approach based on real-time feedback. Planning allows an agent to remain flexible, ensuring it can pivot when conditions change rather than blindly following predefined sequences.
LLMs serve as the reasoning engines of AI agents, showcasing increasingly advanced cognitive abilities. However, they struggle with long-term memory and sustained focus—much like the human mind under information overload. This limitation poses challenges in designing AI agents that must retain context across extended interactions or tackle complex problem-solving tasks.
A critical design question is whether an agent should retain plans internally or offload them to an external tool. Keeping plans within an LLM provides full information access but may be limited by context constraints. For example, an AI managing a real-time chat-based customer support system could benefit from internal memory to dynamically adapt to an ongoing conversation, keeping track of the customer's previous questions and preferences without relying on external systems. This allows the agent to provide personalized responses without the delay of querying an external database. On the other hand, external tools lighten the cognitive load but can introduce rigidity if not well-integrated. For instance, an AI-powered weather application might be better off using an external tool to retrieve up-to-date weather data rather than relying on its internal model, which could become outdated or too complex to manage. This allows the system to focus on processing and presenting the information without overloading its internal resources. A balanced approach ensures adaptability without overloading the agent’s working memory. Ultimately, the necessity of such a tool depends on the LLM's ability to retrieve, retain, and adjust information—an advanced reasoning model might even eliminate the need for external tools.
For example, an AI-powered financial advisor might need to balance long-term investment strategies with short-term market fluctuations. If it relies too heavily on immediate context, it might make impulsive decisions based on temporary trends. On the other hand, if it solely adheres to a rigid external planning framework, it might fail to adapt to new opportunities. The ideal approach blends both—leveraging structured knowledge while maintaining the ability to dynamically reassess and adjust strategies.
Transparent performance management: balancing efficiency and trust
Human-AI agent interaction is shaped by the trade-off between efficiency and trust: the more autonomous an AI agent becomes, the more it can streamline operations and reduce human workload—yet the less transparent its decision-making may feel. In scenarios where tasks are low-risk and repetitive, full automation makes sense as errors have minimal impact, and efficiency gains outweigh the downsides. However, in high-stakes environments like financial trading or medical diagnosis, the costs of a wrong decision are simply too high. Transparent performance management is thus essential.
The challenge is that AI agents, while improving, are still fallible, inheriting issues like hallucinations and biases from LLMs. AI must operate within defined trust thresholds—where automation is reliable enough to act independently yet remains accountable. Rather than requiring continuous human oversight, performance management should focus on designing mechanisms that allow AI agents to function autonomously while ensuring reliability. This involves self-monitoring, self-correction, and explainability.
Mechanisms like agent self-critique mitigate these issues by enabling agents to evaluate their own decisions before execution. Also known as LLM-as-a-judge, self-critique involves sending both input and output to a separate LLM entity that is unaware of the entire agentic workflow, assessing whether the response logically follows from the input. For instance, an LLM can check its output for consistency by sending both its input and response to a separate validation model, which then determines whether the response aligns with the provided information. This process helps catch hallucinations, biases, and inconsistencies before decisions are finalized, improving the reliability of autonomous AI agents.
In the early stages of AI agent deployment, human experts play a crucial role in shaping and refining performance management processes. However, as these agents evolve, the goal is to reduce direct human intervention while maintaining oversight through structured performance metrics. Instead of requiring constant check-ins, AI agents should be designed to self-monitor and adapt, ensuring alignment with objectives without excessive human involvement. By incorporating mechanisms for self-assessment, AI agents can achieve greater autonomy while maintaining accountability. The ultimate aim is to develop fully autonomous agents that balance efficiency with transparency—operating independently while ensuring performance remains reliable.
For example, consider an AI agent managing IT system maintenance in a large enterprise. Such an agent monitors server performance, security threats, and software updates. Instead of relying on human intervention for every decision, it can autonomously detect anomalies, apply minor patches, and optimize system configurations based on historical performance data. However, major decisions—such as deploying a company-wide software update—may still require validation through transparent reporting mechanisms. If the AI agent consistently demonstrates accuracy in its assessments and risk predictions, human involvement can gradually decrease, ensuring both operational efficiency and system integrity.
Transform potential into performance with GenAI
Whether you win or lose in your market may soon rely on having the best GenAI capability and the data foundations to support it. We can help you build this.
Explore our Generative AI servicesWhat’s next for AI agents?
AI agents are evolving beyond simple automation. To become truly intelligent, they must adapt, plan, and learn from experience. Without memory, an agent is static. Without planning, it lacks direction. Without transparent performance management, it risks unreliability.
By integrating memory, planning, and performance management, AI agents can move beyond task execution toward strategic problem-solving. Future AI will not merely automate processes but will actively contribute to decision-making, helping organizations navigate complexity with greater precision and efficiency.
The future belongs to AI that doesn’t just execute tasks but remembers, adapts, and improves. An agent without intelligence is merely automation with an attitude.
Sources
Greenberg DL, Verfaellie M. "Interdependence of episodic and semantic memory: evidence from neuropsychology." J Int Neuropsychol Soc. 2010;16(5):748-753. doi:10.1017/S1355617710000676. Link.
"Does AI Remember? The Role of Memory in Agentic Workflows." (2025) Link.
"RULER: What's the Real Context Size of Your Long-Context Language Models?" (2024). arXiv:2404.06654
This article was written by Gijs Smeets, Data Scientist at Rewire and Mirte Pruppers, Data Scientist at Rewire.
An introduction to the world of LLM output quality evaluation: the challenges and how to overcome them in a structured manner
Perhaps you’ve been experimenting with GenAI for some time now, but how do you determine when the output quality of your Large Language Model (LLM) is sufficient for deployment? Of course, your solution needs to meet its objectives and deliver reliable results. But how can you evaluate this effectively?
In contrast to LLMs, assessing machine learning models is often a relatively straightforward process: metrics like Area Under the Curve for classification or Mean Absolute Percentage Error for regression give you valuable insights in the performance of your model. On the other hand, evaluating LLMs is another ball game, since GenAI generates unstructured, subjective outputs – in the form of texts, images, or videos - that often lack a definitive "correct" answer. This means that you’re not just assessing whether the model produces accurate outputs; you also need to consider, for example, relevance and writing style.
For many LLM-based solutions (except those with very specific tasks, like text translation), the LLM is just one piece of the puzzle. LLM-based systems are typically complex, since they often involve multi-step pipelines, such as retrieval-augmented generation (RAG) or agent-based decision systems, where each component has its own dependencies and performance considerations.
In addition, system performance (latency, cost, scalability) and responsible GenAI (bias, fairness, safety) add more layers of complexity. LLMs operate in ever-changing contexts, interacting with evolving data, APIs, and user queries. Maintaining consistent performance requires constant monitoring and adaptation.
With so many moving parts, figuring out where to start can feel overwhelming. In this article, we’ll purposefully over-simplify things by answering the question: “How can you evaluate the quality of your LLM output?”. First, we explain what areas you should consider in the evaluation of the output. Then, we’ll discuss the methods needed to evaluate output. Finally, to make it concrete, we bring everything together in an example.
What are the evaluation criteria of LLM output quality?
High-quality outputs build trust and improve user experience, while poor-quality responses can mislead users and foster misinformation. The start of building an evaluation (eval) is to start with the end-goal of the model. The next step is to define the quality criteria to be evaluated. Typically these are:
- Correctness: Are the claims generated by the model factually accurate?
- Relevance: Is the information relevant to the given prompt? Is all required information provided -by the end user, or in the training data- to adequately offer an answer to the given prompt?
- Robustness: Does the model consistently handle variations and challenges in input, such as typos, unfamiliar question formulations, or types of prompts that the model was not specifically instructed for?
- Instruction and restriction adherence: Does the model comply with predefined restrictions or is it easily manipulated to jailbreak the rules?
- Writing style: Does the tone, grammar, and phrasing align with the intended audience and use case?
How to test the quality of LLM outputs?
Now that we’ve identified what to test, let’s explore how to test. A structured approach involves defining clear requirements for each evaluation criterion listed in the previous section. There are two aspects to this: references to steer your LLM towards the desired output and the methods to test LLM output quality.
1. References for evaluation
In LLM-based solutions, the desired output is referred to as the golden standard, which contain reference answers for a set of input prompts. Moreover, you can provide task-specific guidelines such as model restrictions and evaluate how well the solution adheres to those guidelines.
While using a golden standard and task-specific guidelines can effectively guide your model towards the desired direction, it often requires a significant time investment and may not always be feasible. Alternatively, performance can also be assessed through open-ended evaluation. For example, you can use another LLM to assess relevance, execute generated code to verify its validity, or test the model on an intelligence benchmark.
2. Methods for assessing output quality
Selecting the right method depends on factors like scalability, interpretability, and the evaluation requirement being measured. In this section we explore several methods, and assess their strengths and limitations.
2.1. LLM-as-a-judge
An LLM isn’t just a text generator—it can also assess the outputs of another LLM. By assessing outputs against predefined criteria, LLMs provide an automated and scalable evaluation method.
Let’s demonstrate this with an example. For example, ask the famous question, "How many r's are in strawberry?" to ChatGPT's 4o mini model. It responds with, "The word 'strawberry' contains 1 'r'.", which is obviously incorrect. With the LLM-as-a-judge method, we would like the evaluating LLM (in this case, also 4o mini) to recognize and flag this mistake. In this example, there is a golden reference answer “There are three 'r’s' in 'strawberry'.”, which can be used to evaluate the correctness of the answer.
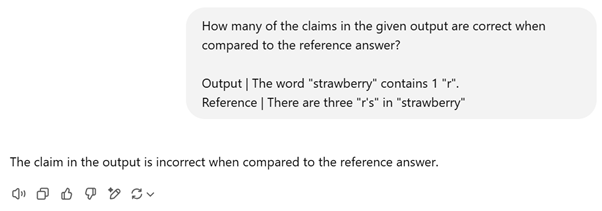
Indeed, the evaluating LLM appropriately recognizes that the answer is incorrect.
The example shows that LLMs can evaluate outputs consistently and at scale due to their ability to quickly assess several criteria. On the other hand, LLMs may struggle to understand complex, context-dependent nuances or subjective cases. Moreover, LLMs may strengthen biases within the training data and can be costly to use as an evaluation tool.
2.2. Similarity metrics for texts
When a golden reference answer is available, similarity metrics provide scalable and objective assessments of LLM performance. Famous examples are NLP metrics like BLEU and ROUGE, or more advanced embedding-based metrics like cosine similarity and BERTScore. These methods provide quantitative insights in measuring the overlap in words and sentence structure without the computational burden of running full-scale LLMs. This can be beneficial when outcomes must closely align with provided references – for example in the case of summarization or translation.
While automated metrics provide fast, repeatable, and scalable evaluations, they can fall short on interpretability and often fail to capture deeper semantic meaning and factual accuracy. As a result, they are best used in combination with human evaluation or other evaluation methods.
2.3. Human evaluation
Human evaluation provides a strong evaluation method due to its flexibility. In early stages of model development, it is used to thoroughly evaluate errors such as hallucinations, reasoning flaws, and grammar mistakes to provide insights into model limitations. As the model improves through iterative development, groups of evaluators can systematically score outputs on correctness, coherence, fluency, and relevance. To reduce workload and enable real-time human evaluation after deployment, pairwise comparison can be used. Here, two outputs are compared to determine which performs better for the same prompt. This is in fact implemented in ChatGPT.
It is recommended to use both experts as non-experts in human evaluation of your LLM. Experts can validate the model’s approach based on their expertise. On the other hand, non-experts play a crucial role in identifying unexpected behaviors and offering fresh perspectives on real-world system usage.
While human evaluation offers deep, context-aware insights and flexibility, it is resource- and time-intensive. Moreover, comparing different examiners can lead to inconsistent evaluations when they are not aligned.
2.4. Benchmarks
Lastly, there are standardized benchmarks that offer an approach to assess the general intelligence of LLMs. These benchmarks evaluate models on various capabilities, such as general knowledge (SQuAD), natural language understanding (SuperGLUE), and factual consistency (TruthfulQA). To maximize their relevance, it’s important to select benchmarks that closely align with your domain or use case. Since these benchmarks test broad abilities, they are often used to identify an initial model for prototyping. However, standardized benchmarks can provide a skewed perspective due to their lack of alignment with your specific use case.
2.5. Task specific evaluation
Depending on the task, other evaluation methods are appropriate. For instance, when testing a categorization LLM, accuracy can be measured using a predefined test set alongside a simple equality check (of the predicted category vs. actual category). Similarly, the structure of outputs can be tested by counting line-breaks; certain headers and/or the presence of certain keywords can also be checked. Although these technique are not easily generalizable across different use cases, they offer a precise and efficient way to verify model performance.
Putting things together: writing an eval to measure LLM summarization performance
Consider a scenario where you're developing an LLM-powered summarization feature designed to condense large volumes of information into three structured sections. To ensure high-quality performance, we evaluate the model for each of our five evaluation criteria. For each criterion, we identify a key question that guides the evaluation. This question helps define the precise metric needed and determines the appropriate method for calculating it.
| Criterium | Key question | Metric | How |
| Correctness | Is the summary free from hallucinations? | Number of statements in summary that can be verified based on source text | * Use an LLM-as-a-judge to check if each statement can be answered based on the source texts * Use human evaluation to verify correctness of outputs |
| Relevance | Is the summary complete? | Number of key elements present with respect to a reference guideline or golden standard summary | Cross-reference statements in summaries with LLM-as-a-judge and measure the overlap |
| Is the summary concise? | Number of irrelevant statements with respect to golden standard Length of summary | * Cross-reference statements in summaries with LLM-as-a-judge and measure the overlap * Count the number of words of generated summaries | |
| Robustness | Is the model prone to noise in the input text? | Similarity of summary generated for original text with respect to summary generated for text with noise such as typo’s and inserted irrelevant information | Compare statements with LLM-as-a-judge, or compare textual similarity with ROUGE or BERTscore |
| Instruction & restriction adherence | Does the summary comply with required structure? | Presence of three structured sections | Count number of line breaks and check presence of headers |
| Writing style | Is the writing style professional, fluent and free of grammatical errors? | Rating of tone-of-voice, fluency and grammar | * Ask LLM-as-a-judge to rate fluency and professionality and mark grammatical errors * Rate writing style with human evaluation |
| Overarching: alignment with golden standard | Do generated summaries align with golden standard summaries? | Textual similarity with respect to golden standard summary | Calculate similarity with ROUGE or BERTscore |
The table shows that the proposed evaluation strategy leverages multiple tools and combines reference-based and reference-free assessments to ensure a well-rounded analysis. And so we ensure that our summarization model is accurate, robust, and aligned with real-world needs. This multi-layered approach provides a scalable and flexible way to evaluate LLM performance in diverse applications.
Final thoughts
Managing LLM output quality is challenging, yet crucial to build robust and reliable applications. To ensure success, here are a few tips:
- Proactively define the evaluation criteria. Establish clear quality standards before model deployment to ensure a consistent assessment framework.
- Automate when feasible. While human evaluation is essential for subjective aspects, automate structured tests for efficiency and consistency.
- Leverage GenAI to broaden your evaluation. Use LLMs to generate diverse test prompts, simulate user queries, and assess robustness against variations like typos or multi-language inputs.
- Avoid reinventing the wheel. There are already various evaluation frameworks available on the internet (for instance, DeepEval). These frameworks provide structured methodologies that combine multiple evaluation techniques.
Achieving high-quality output is only the beginning. Generative AI systems require continuous oversight to address challenges that arise after deployment. User interactions can introduce unpredictable edge cases, exposing the gap between simulated scenarios and real-world usage. In addition, updates to models and datasets can impact performance, making continuous evaluation crucial to ensure long-term success. At Rewire, we specialize in helping organizations navigate the complexities of GenAI, offering expert guidance to achieve robust performance management and deployment success. Ready to take your GenAI solution to the next level? Let’s make it happen!
This article was written by Gerben Rijpkema, Data Scientist at Rewire, and Renske Zijm, Data Scientist at Rewire.
Turning Generative AI potential into bottom line impact
Our strategies enable you to harness generative AI, moving beyond marginal or tactical gains to achieve transformational success.
Explore our Generative AI services